• **Fourier / smoothness (the quadratic prior)** — penalize energy in high frequencies: $\Phi(x)=\lVert x\rVert^2$ or $\lVert \nabla x\rVert^2$ (Tikhonov). **Linear, closed-form** (the solve diagonalizes in Fourier → a Wiener-type filter, [[Blind deblurring]]). The cheapest prior — and the bluntest: it **over-smooths and kills edges**, because it treats a sharp edge as just expensive high frequency.
• **Wavelets, etc. — sparsity in a transform basis** — natural images are **sparse** in a multi-scale basis (wavelets, later curvelets/shearlets): a few large coefficients, the rest ~0. Penalize $\lVert Wx\rVert_1$ → coefficient **thresholding / shrinkage**, basis pursuit, sparse coding. **Edge-preserving** (an edge is a handful of big coefficients, not broadband energy) and the historical root of compressive sensing's $\ell_1$ recovery (cross-ref [[Computational optics and coded imaging#Compressive sensing]]).
• **Anisotropic signal — sparsity made geometric** — **total variation** $\lVert\nabla x\rVert_1$ (Rudin–Osher–Fatemi): sparse *gradients* ⇒ **piecewise-smooth** images with crisp discontinuities; the continuous-time cousin is **anisotropic diffusion** (Perona–Malik — smooth *along* edges, not across). Same "sparsity" idea as wavelets but stated on the **image gradient / geometry**, so it adapts to oriented structure (the "anisotropic" part).
• **Gradients — natural-image gradient statistics** — measure real images and the gradient histogram is **heavy-tailed** (mostly tiny, rare huge): a **sparse-gradient / hyper-Laplacian** prior $\sum|\nabla x|^\alpha,\ \alpha<1$ (Levin et al. 2007; Krishnan & Fergus 2009). This is the prior that breaks the **blind-deblurring** tie ([[Blind deblurring]]) and underwrites gradient-domain editing ([[Poisson image editing]]). TV is its convex ($\alpha=1$) special case.
• **Dead leaves — a *generative* model of the statistics** — every rung above *measures* image statistics and penalizes departures; the **dead-leaves model** instead *generates* them. Drop opaque shapes of random size and intensity one over another (a power-law size distribution) and **occlusion alone** reproduces the $1/f$ spectrum, **scale invariance**, and the heavy-tailed edge/gradient statistics (Matheron's random sets; Lee, Mumford & Huang 2001; Ruderman 1997). It is the classical bridge from *describing* natural images to *modeling* them — the hand-built ancestor of the **learned** generative priors at the bottom of this list (diffusion). Not a penalty you plug into a solver, but the model that explains *why* the gradient/spectral penalties above are the right ones.
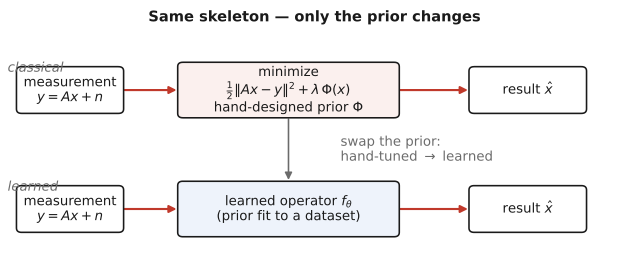
• **Learned filters — fit the penalty to data** — stop *hand-choosing* the basis/penalty and **learn** it: **Fields of Experts** (a Markov random field of learned filter responses, Roth & Black), **dictionary learning / K-SVD** (learn an overcomplete sparsifying dictionary), **trainable reaction–diffusion** (unroll a few diffusion steps and learn their filters). The prior is now **parametric and data-driven**, but still a stand-alone regularizer you plug into the same data-fit + prior solve.
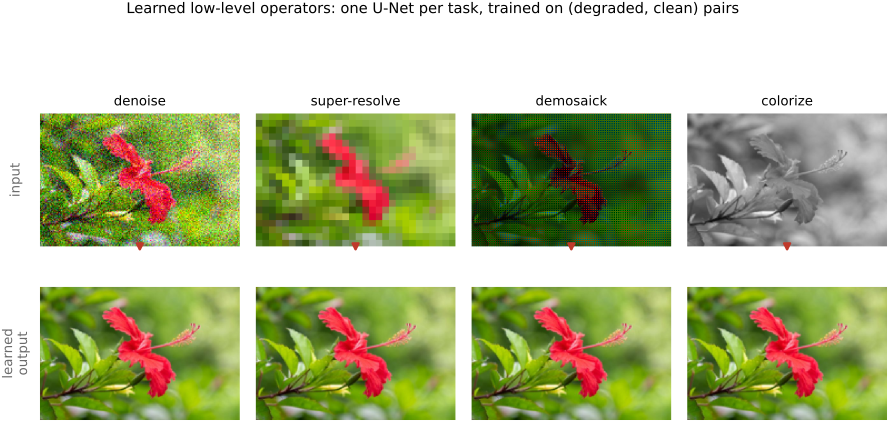
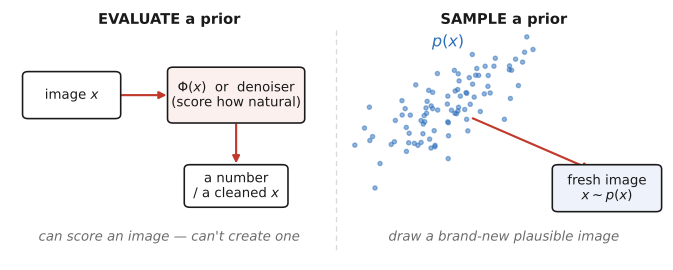
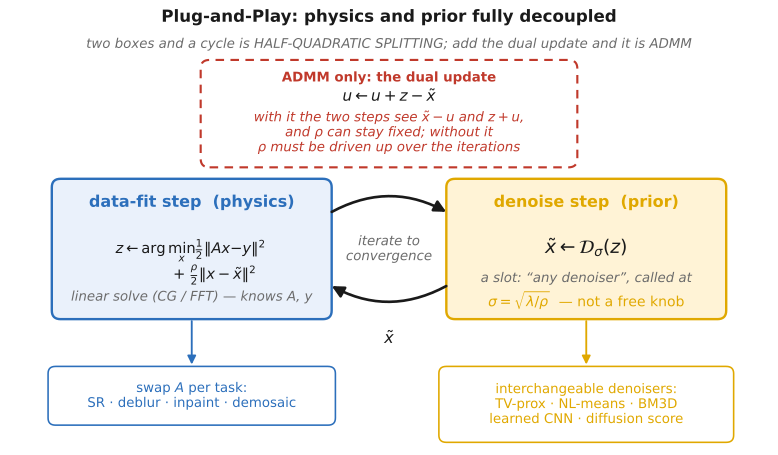
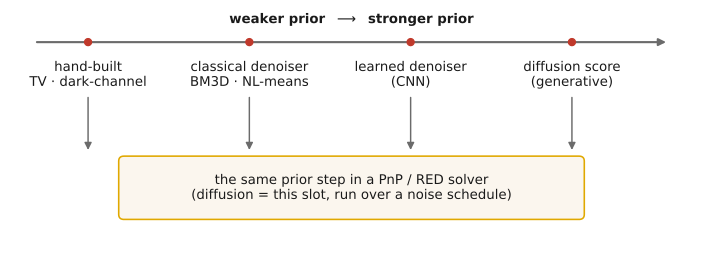
• **Denoising — the universal prior** — the limit of the previous rung: a *denoiser* already encodes "what natural images look like," so **any denoiser is a prior** (PnP / RED — next section). The catalog's hand-built penalties (Fourier, TV, wavelet, gradient) are just *explicit, weak denoisers*; classical (BM3D, NL-means) and learned (CNN) denoisers are stronger ones in the **same slot**.
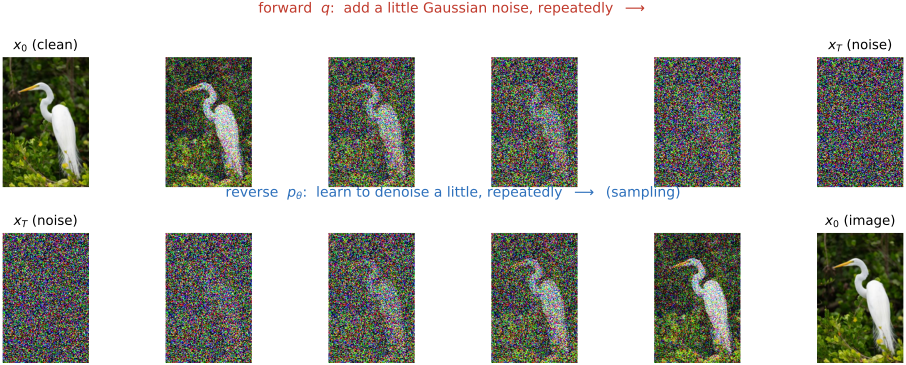
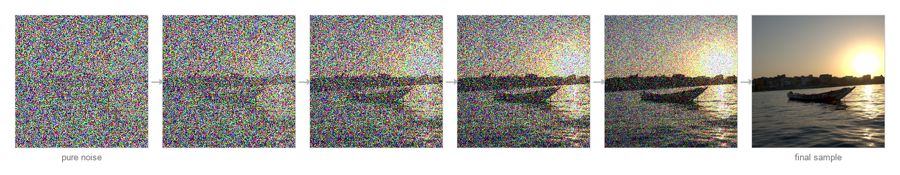
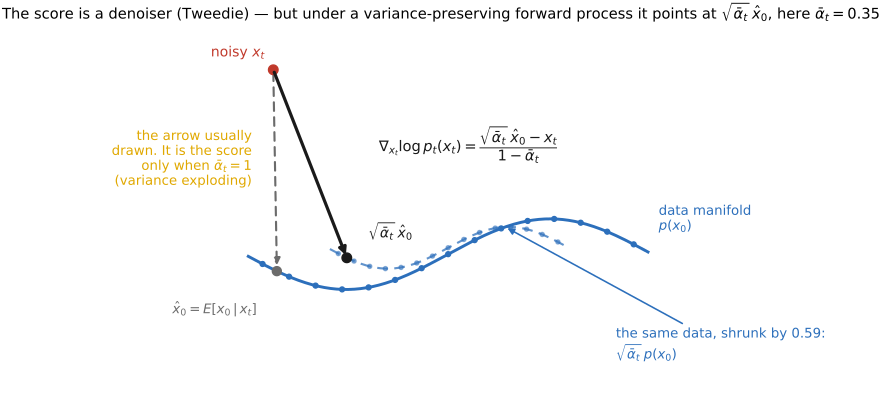
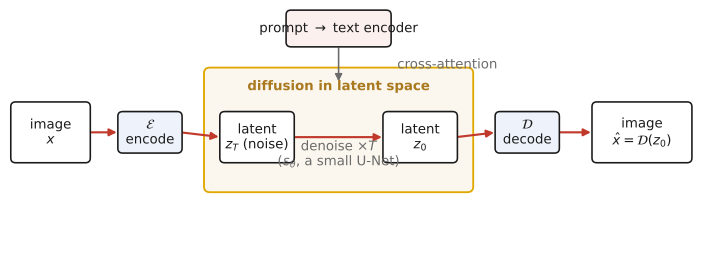
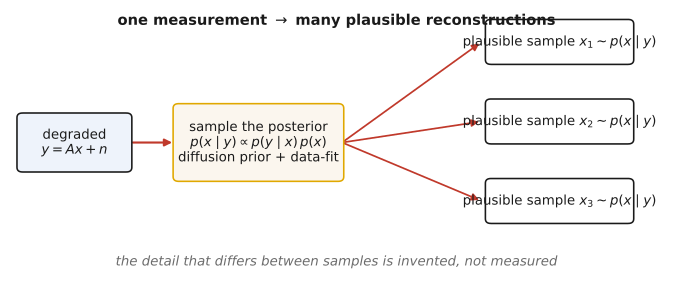
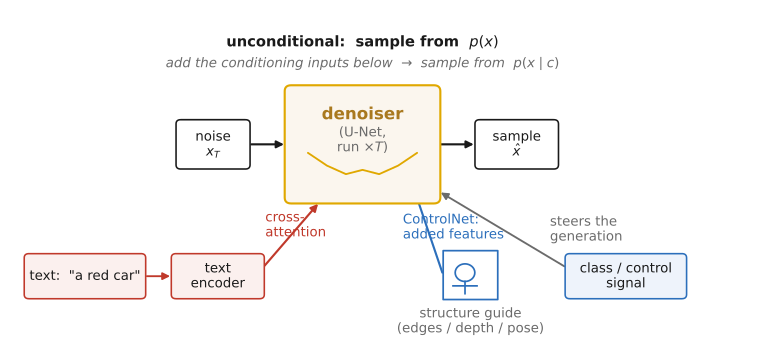
• **Diffusion — the strongest learned prior** — a denoiser trained over *all* noise levels, applied iteratively (next-but-one section): the most expressive point on the axis, the score of the natural-image distribution itself.
• **Joint learning — learn the inversion *and* the prior together** — the final move: stop treating the prior as a separable module. **Unroll** the iterative solver into a fixed number of steps and train the *whole reconstruction network* end-to-end on (measurement, ground-truth) pairs — **LISTA** (Gregor & LeCun), **ADMM-Net** (Yang et al.), **ISTA-Net** (Zhang & Ghanem), deep equilibrium / learned PnP. The "prior" is no longer something you can write down — it is **whatever weights make this forward operator's inversion best**, co-adapted to the physics $A$. (Cross-ref [[Deep learning]] — learned-operator lesson; and end-to-end optics+recovery in [[Computational optics and coded imaging#End-to-end optimization]].)
• 💡 **the arc**: fixed basis (Fourier) → fixed sparsity (wavelet/TV/gradient) → learned penalty (FoE/dictionary) → learned denoiser (PnP) → learned distribution (diffusion) → **prior + inversion learned jointly**. Each step trades **interpretability for expressiveness** (and needs more data). The next section shows the whole middle of this list is *one operation* — denoising.