28.9 Personalized priors⧉
A prior is whatever a model assumes about the answer before it sees the degraded or missing input. Restoring or generating a face is ill-posed, so the prior often determines the result: the input narrows the space of answers, and the prior picks among everything that survives. A generic image prior, trained on everyone, knows what a face looks like, and it will fill an eight-pixel-wide blur or a missing region with the most statistically plausible face it can. A personalized prior knows what your face looks like, and can constrain the same gap using your reference photographs, though it can still synthesize incorrect details. When the task is to recover or depict a specific, recognizable subject, those are not small differences in quality: they are different people, and only one of them is correct.
The wager is the same one the rest of this part keeps making, just aimed at a single person instead of the whole world. Chapter 21.3, Inpainting Using Millions of Photographs bet that, at the scale of millions of photographs, some image already contains a plausible completion of almost any scene; Chapter 28.8, Pix 2 GPS bet that a giant geotagged corpus is a model of how the planet looks. Personalized priors make the inverse bet: the collection is tiny (a handful to a few dozen of someone's own photographs), but it is exactly the right collection, and for the narrow job of being about that subject it beats a model trained on everyone. Scale is traded for specificity, and for restoring or synthesizing a particular person, specificity is what matters.
28.9.1 Personalized restoration⧉
Super-resolution, denoising, and deblurring are all instances of the same ill-posed inverse problem from Chapter 14.1, What can super-resolution actually do?: a forward model threw away information through blur, downsampling, and noise, and infinitely many sharp images are consistent with the degraded one you hold. The prior is what chooses. A generic face prior (a GAN or diffusion model trained on thousands of faces) chooses the most plausible face in general: it will happily synthesize a crisp, symmetric, attractive face that has nothing to do with the person actually in the photo. It looks sharp and it looks like a face, and that is what makes the failure dangerous: the hallucinated detail is plausible, just wrong, the same distinction between plausible detail and recovered evidence discussed in Chapter 14.1, What can super-resolution actually do?.
A personalized restoration prior closes that gap by feeding the model the subject's own clean photographs (high-resolution, well-exposed captures of the same person) as exemplars or as an explicit identity constraint. Now the model is not asked to invent eyes from the population average; it has evidence about eye shape, the mole on the left cheek, the asymmetric hairline, the way this particular face creases when it smiles: identity-specific evidence that a population prior alone may not provide. The restoration still needs to distinguish stable features from expression, age, pose, and lighting changes in the references. The collection acts as a per-subject memory that the restoration is allowed to copy from (Figure 28.9.1).
Specificity helps for one reason. Both priors are "correct" in the weak sense that both produce a sharp, face-shaped output consistent with the blurry input. For a known person, the goal is identity fidelity, not just plausibility. The generic prior maximizes the likelihood of the output under "faces in general"; the personalized prior maximizes it under "this specific face." A stranger also has a specific identity; being unfamiliar with it only makes errors harder for the viewer to notice. For someone recognizable (and recognizability is the only reason you cared to restore the photo), they diverge sharply, and a useful evaluation tests both identity similarity and consistency with the actual degraded observation.
28.9.2 Personalizing generative models⧉
The same move powers a more recent and more visible application: teaching a large pretrained generative model a new subject from a few example images, so it can then place that subject in scenes and styles it never photographed. This is the generative version of the same idea: instead of recovering lost pixels of a known person, you synthesize novel pixels of them, and it leans on the same insight that a tiny personal set, folded into the model, beats anything the generic model knew on its own. Two methods define the space, and they sit at opposite ends of a cost/fidelity trade-off.
DreamBooth (Ruiz et al., 2023) Ruiz et al. 2023 (DreamBooth) fine-tunes the model's weights. Take a pretrained text-to-image diffusion model (Chapter 7.3, Deep learning), bind the subject to a rare, unique token ("a photo of a [V] person"), and continue training on just a handful, often three to five, images of the subject. The weights shift just enough to associate that token with this specific identity, so afterward a prompt like "a [V] person as an astronaut" renders that person in a spacesuit. To keep the fine-tuning from collapsing the whole class onto one face, which would weaken the model's general notion of a person, DreamBooth adds a prior-preservation loss that interleaves generic examples of the class, a telling acknowledgment that personalization is a deliberate, controlled overfitting.
Textual inversion (Gal et al., 2022) is the lighter-weight cousin: it freezes the model entirely and instead learns a single new embedding (a new pseudo-word in the model's vocabulary) that, when fed to the unchanged network, summons the subject. Nothing about the model's weights changes; all the new knowledge lives in one learned vector that you can save, share, and drop into prompts. It is cheaper, more portable, and less prone to damaging the base model, at some cost in fidelity for hard subjects. Both methods do the same essential thing (encode a person or object into a generative prior from a tiny personal set) and differ only in where they put the new knowledge: DreamBooth in the weights, textual inversion in a learned embedding while the pretrained generator remains frozen.
28.9.3 The bargain and its ethics⧉
The recurring empirical finding is blunt: for restoring or synthesizing a specific subject, personalization can improve identity fidelity, depending on the references and method, and it pays for that win twice. It pays in generality, because weight fine-tuning can degrade the base model’s class representation (the reason DreamBooth needs its prior-preservation loss). And it pays in overfitting and memorization: a prior built from a dozen images can simply regurgitate them, reproducing a training photo's background, pose, or lighting wholesale instead of generalizing: the personal-scale version of the same memorization risk that haunts large generative models. The specificity that makes the prior good is inseparable from the specificity that makes it brittle.
The deeper cost is ethical, and it is not a side note; it follows directly from the method's success. A model that faithfully reproduces a particular person is, by construction, a tool for impersonation: the very identity fidelity that lets you restore Grandmother's blurred portrait also lets someone synthesize a convincing photograph of a person doing something they never did. The same technical capability supports authorized depictions and nonconsensual impersonation. Consent and the intended use do not follow from a model’s ability to reproduce a likeness. So the central questions become consent, ownership, and likeness: whose photos may be used to build whose prior, who may invoke it, and what recourse a person has against a faithful synthetic double. This is the personal-scale echo of the always-on privacy problem in Chapter 28.4, Life logging cameras: there, the harm was a camera that recorded everyone without asking; here, it is a model that can depict anyone without asking.
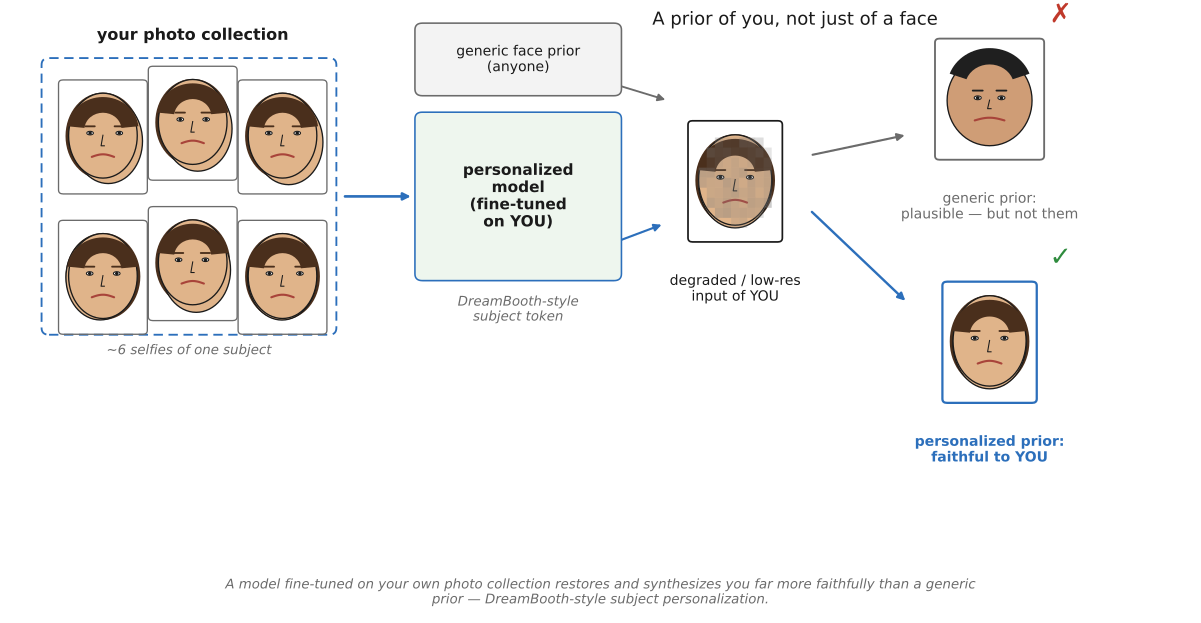
For an ill-posed problem, the prior decides the answer, so for restoring or depicting a specific person, the right prior is their own photographs. A generic model trained on everyone fills the gap with the most plausible anyone; a personalized model trained on a tiny personal collection fills it with the actual you. This is the part's data-as-prior creed (Chapter 21.3, Inpainting Using Millions of Photographs, Chapter 28.8, Pix 2 GPS) turned inward: the collection shrinks from millions of strangers' photos to a dozen of your own, and that shrinkage is the point: the collection is small but exactly the right one. The same specificity that buys identity fidelity (over the generic average) also buys overfitting, memorization, and a consent problem, because a faithful model of one person is, unavoidably, a tool for impersonating them.
Recap: big lessons of this chapter
For an ill-posed problem, the prior decides the answer, so for restoring or depicting a specific person, the right prior is their own photographs. A generic model trained on everyone fills the gap with the most plausible anyone; a personalized model trained on a tiny personal collection fills it with the actual you. This is the part's data-as-prior creed (Chapter 21.3, Inpainting Using Millions of Photographs, Chapter 28.8, Pix 2 GPS) turned inward: the collection shrinks from millions of strangers' photos to a dozen of your own, and that shrinkage is the point: the collection is small but exactly the right one. The same specificity that buys identity fidelity (over the generic average) also buys overfitting, memorization, and a consent problem, because a faithful model of one person is, unavoidably, a tool for impersonating them.