12.11 Body pose estimation⧉
Move from the face to the whole body and the problem becomes articulated: a person is a kinematic chain of joints, and pose estimation recovers a skeleton of keypoints, such as head, shoulders, elbows, wrists, hips, knees, and ankles, for every person in the frame, and increasingly a full 3-D body mesh. It is correspondence once more, but now between the image and a known articulated model of the human body: instead of "where did this pixel go," the question is "where is each named joint." The standard 2-D target is the COCO Lin et al. 2014 (COCO) 17-keypoint skeleton; hands (21 points each) and face extend it to whole-body pose.
12.11.1 Top-down vs bottom-up⧉
Top-down pose estimates joints inside detected person crops and inherits missed detections. Its inference cost usually grows with the number of crops. Bottom-up methods detect joint candidates across the image, then group them into people. The main network cost can be largely fixed at a given resolution, but grouping cost and ambiguity grow with crowding. OpenPose uses part-affinity fields for this association Cao et al. 2017 (OpenPose); HRNet maintains high-resolution features alongside lower-resolution branches Sun et al. 2019 (HRNet). Neither design guarantees success on overlapping people. Both descend from DeepPose Toshev & Szegedy 2014 (DeepPose), the first system to regress joint coordinates directly with a deep network; most later methods predict a heat map per joint instead, which localizes more precisely than a single regressed coordinate.
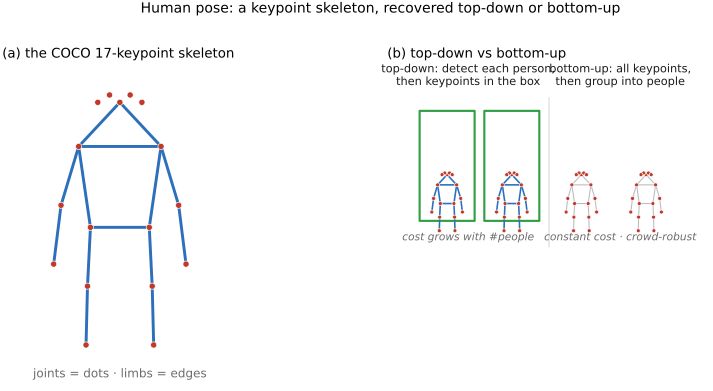
In a crowded photograph, a top-down system can fail before estimating any joints if its person detector misses a partly occluded body. A bottom-up system may detect the elbow and wrist yet pair them with different people. These are different failure locations: finding the person versus associating parts. Part-affinity fields supply evidence along the proposed limb connection rather than relying only on proximity. Inspecting person boxes, joint heatmaps, and associations separately makes the architecture's failure understandable (Figure 12.11.1).
12.11.2 On-device, real time⧉
The documented MediaPipe Pose Landmarker estimates 33 landmarks Bazarevsky et al. 2020 (BlazePose), with image and world-coordinate outputs. Record the coordinate conventions and the model bundle. Those outputs are inferred from a camera image; they are not equivalent to measured metric motion capture. Hands and face need their own detailed landmark models when the application requires them. MediaPipe's hand model returns 21 landmarks per hand, and its Holistic solution runs the body, hand and face models together so that one camera yields a whole-person skeleton; each part keeps its own layout and coordinate convention.
12.11.3 Lifting to 3-D: parametric bodies⧉
A 2-D skeleton underdetermines depth, scale and some joint configurations. SMPL supplies a shape/pose model Loper et al. 2015 (SMPL), and HMR estimates its parameters from an image Kanazawa et al. 2018 (HMR). The prior chooses among plausible bodies; it does not remove the ambiguity of the observation. Occluded limbs and loose clothing can disagree with the inferred mesh. Evaluate any quantitative motion measurement against suitable reference data.
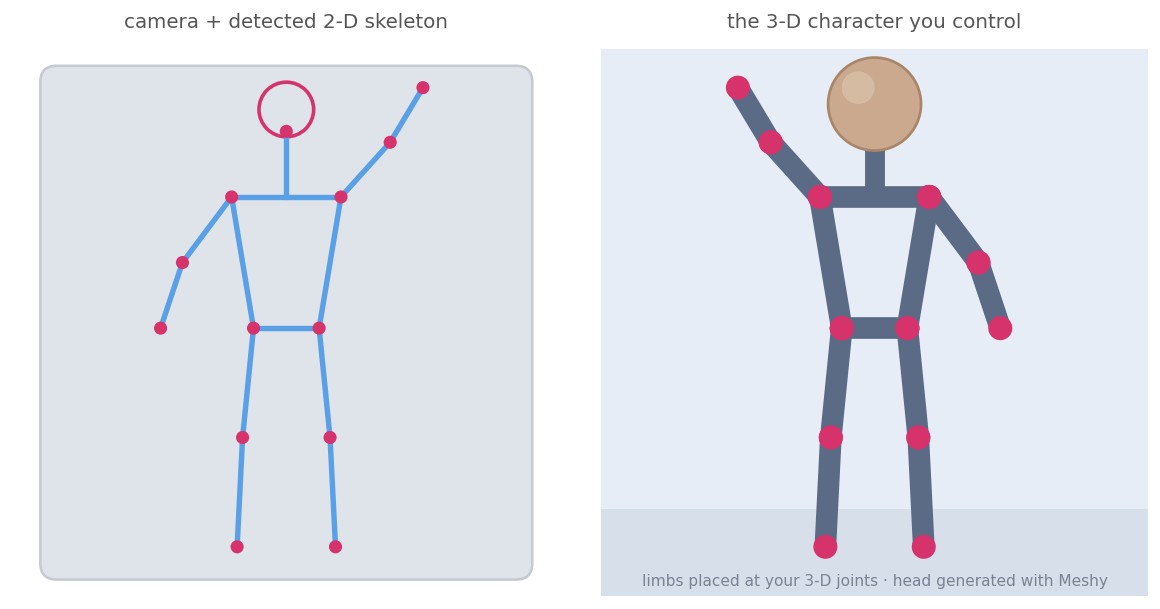
SMPL maps a shape vector describing body build and pose parameters describing articulation to a complete mesh. That compact representation lets an application render an avatar, transfer a motion or compare pose over time. HMR predicts those parameters from the image rather than asking the application to manipulate every mesh vertex. The distinction between an observed joint, an inferred hidden joint and a rendered surface matters when the same output is used for animation, virtual try-on or motion measurement.
12.11.4 Which library to use optional⧉
Use the Pose Landmarker guide for a packaged on-device starting point. The other toolkits differ by role. OpenPose is the reference implementation of the bottom-up, part-affinity approach. MMPose and Detectron2 are research frameworks with many top-down and bottom-up models (HRNet among them) and their evaluation code; AlphaPose is a top-down multi-person system. Check each project's maintenance status and the license of its pretrained weights, some of which exclude commercial use. For research comparisons, record the detector, keypoint layout and evaluation protocol. Benchmark the complete pipeline at the intended person count; detector, grouping and temporal association costs matter alongside network inference.