28.5 Photo tourism⧉
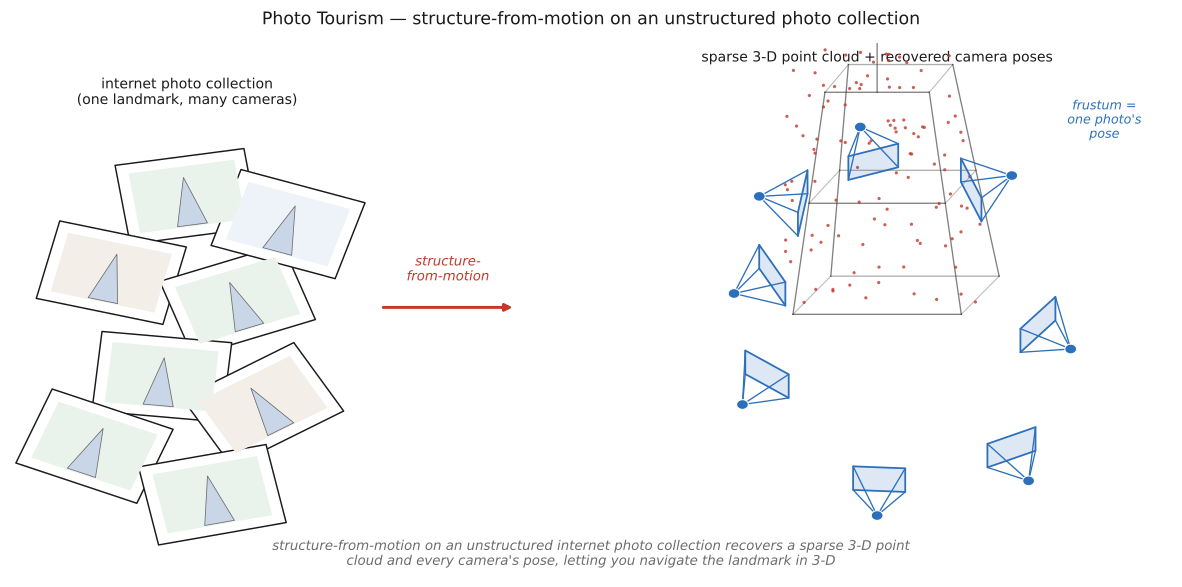
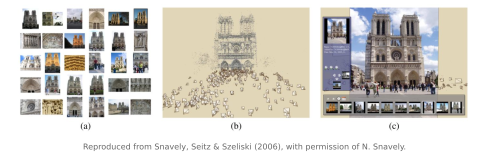
Type "Notre-Dame" or "Trevi Fountain" into a photo-sharing site and you get back tens of thousands of photographs taken by strangers who never coordinated with one another: every lens, every season, every time of day, every accidental tourist in the foreground. It looks like noise: a pile of redundant snapshots with no shared frame of reference. Snavely, Seitz and Szeliski's Photo Tourism (2006) Snavely et al. 2006 made the claim that this pile is secretly a 3-D capture rig. Run structure-from-motion (SfM) over it and you recover, jointly from image correspondences, aided by camera metadata when available, a sparse 3-D point cloud of the landmark and the camera pose (position and orientation) of the photos that can be registered, all in one coordinate frame. The collection stops being a heap of pictures and becomes a navigable place: click a window of the cathedral and the system glides you to the photograph that best shows it. The technique is foundational multi-view geometry; the data is the crowd's. Productised as Microsoft Photosynth, it became the public face of the idea that an unstructured internet photo collection is enough to reconstruct the world.
28.5.1 Structure-from-motion on internet collections⧉
What makes the problem hard is precisely what makes the data free: the input is unstructured. A traditional 3-D scanner, such as a calibrated stereo rig, a turntable, or a laser scanner, controls the cameras, the lighting, and the geometry, and knows its own parameters in advance. Photo Tourism is handed none of that. Its input is thousands of strangers' photos, each shot with an unknown camera at an unknown focal length, cropped and post-processed however the photographer pleased, under whatever weather and crowd happened to be there that day. Two photos of the same statue might be taken a decade apart, from opposite sides, one at noon and one at dusk, one with a wide lens and one zoomed in. The reconstruction has to discover the cameras' parameters and the scene and who was standing where, all at once, from this wild heterogeneity, and it must do so while most candidate feature matches between any two photos are simply wrong.
The pipeline assembles tools from earlier in the book. First, detect and match features across image pairs: extract SIFT keypoints in every photo and match them by nearest neighbor in descriptor space (Chapter 12.3, Sparse matching). SIFT's scale and rotation invariance is not a luxury here; it is the reason a feature on the rose window can be matched between a wide establishing shot and a tight zoom. Second, robustly estimate two-view geometry: for each promising pair of photos, fit the fundamental matrix $F$, the $3\times3$ matrix encoding the epipolar geometry between two uncalibrated views (Part 36, 3D and depth), inside a RANSAC loop that rejects the many outlier matches as it goes (Chapter 12.5, Robustness: the ratio test and RANSAC). The ratio test prunes the ambiguous matches before fitting; RANSAC fits $F$ to a consensus of geometrically consistent inliers and discards the rest. A pair with a large, stable inlier set is evidence of overlap, although repeated structures can still produce false matches; a pair that does not is set aside. The output of this stage is a graph of photos connected by verified geometric relationships.
Third, reconstruct incrementally. In the incremental approach used here, rather than initializing all cameras at once, the system seeds the reconstruction from one well-matched pair, triangulates their shared inliers into initial 3-D points, and then adds cameras one at a time: each new photo brought in by matching its features to the points already reconstructed and solving for its pose. After every addition (and periodically over the whole set) it runs bundle adjustment: a large nonlinear least-squares optimization that jointly refines all the 3-D point positions, all the camera poses, and all the camera intrinsics (focal length and distortion) to minimize the total reprojection error, the gap between where each 3-D point lands when projected into a photo and where its matched feature actually was observed (Triggs et al. 2000 Triggs et al. 2000; Part 36, 3D and depth). Bundle adjustment is the glue that keeps a growing reconstruction globally consistent; without it, small per-camera errors accumulate and the cloud drifts.
The result, drawn in the figure, is twofold. There is a sparse 3-D point cloud of the landmark (every triangulated feature a point in space), and there is a recovered camera frustum for each registered photo: a little pyramid marking where that photographer stood and which way they pointed, all in one shared coordinate frame. The registered snapshots have been placed in a common coordinate frame. Without metric references, a standard calibrated reconstruction is determined only up to an overall similarity transform, including scale. Figure 28.5.1.
28.5.2 From reconstruction to experience⧉
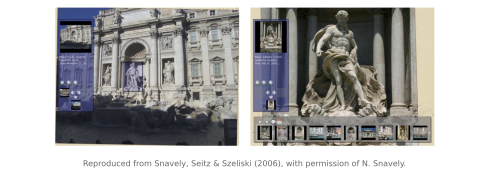
The geometry is the means; the experience is the point, and it is what made Photo Tourism a landmark beyond the SfM literature. Once every photo's pose is known, the collection becomes spatially browsable. You can fly a virtual camera through the point cloud, and for any viewpoint the system can snap to the real photograph whose recovered pose best matches your current viewpoint, so navigating the 3-D model is really navigating through other people's photographs of the place. Click a detail in one image and it understands, geometrically, which other photos show that same detail better, and offers to take you there. A flat gallery of unrelated snapshots becomes a coherent tour. Photosynth productised exactly this: upload a set of photos of a scene, get back a navigable synth.
The transitions are where the geometry earns its keep. Moving from one photo to another is not a hard cut or a dissolve; it is a 3-D-aware morph that uses the recovered cameras and points to interpolate a plausible in-between view: warping the source image toward the destination along the geometry rather than fading between two unrelated frames. The effect is that the collection feels like a continuous space you move smoothly through, not a slideshow you click between. This is the same "collection becomes an experience" idea that animates Chapter 28.6, Photobios, where a personal set of portraits is morphed into a continuous time-lapse of an aging face. There the collection is one person across years and the navigable dimension is time; here the collection is a crowd at one place and the navigable dimension is space, but the move is identical: align a messy real collection to a shared frame, then let the data, not a synthetic model, supply the in-betweens.
The browsing-and-transition experience is best seen in motion in the original Photo Tourism video.
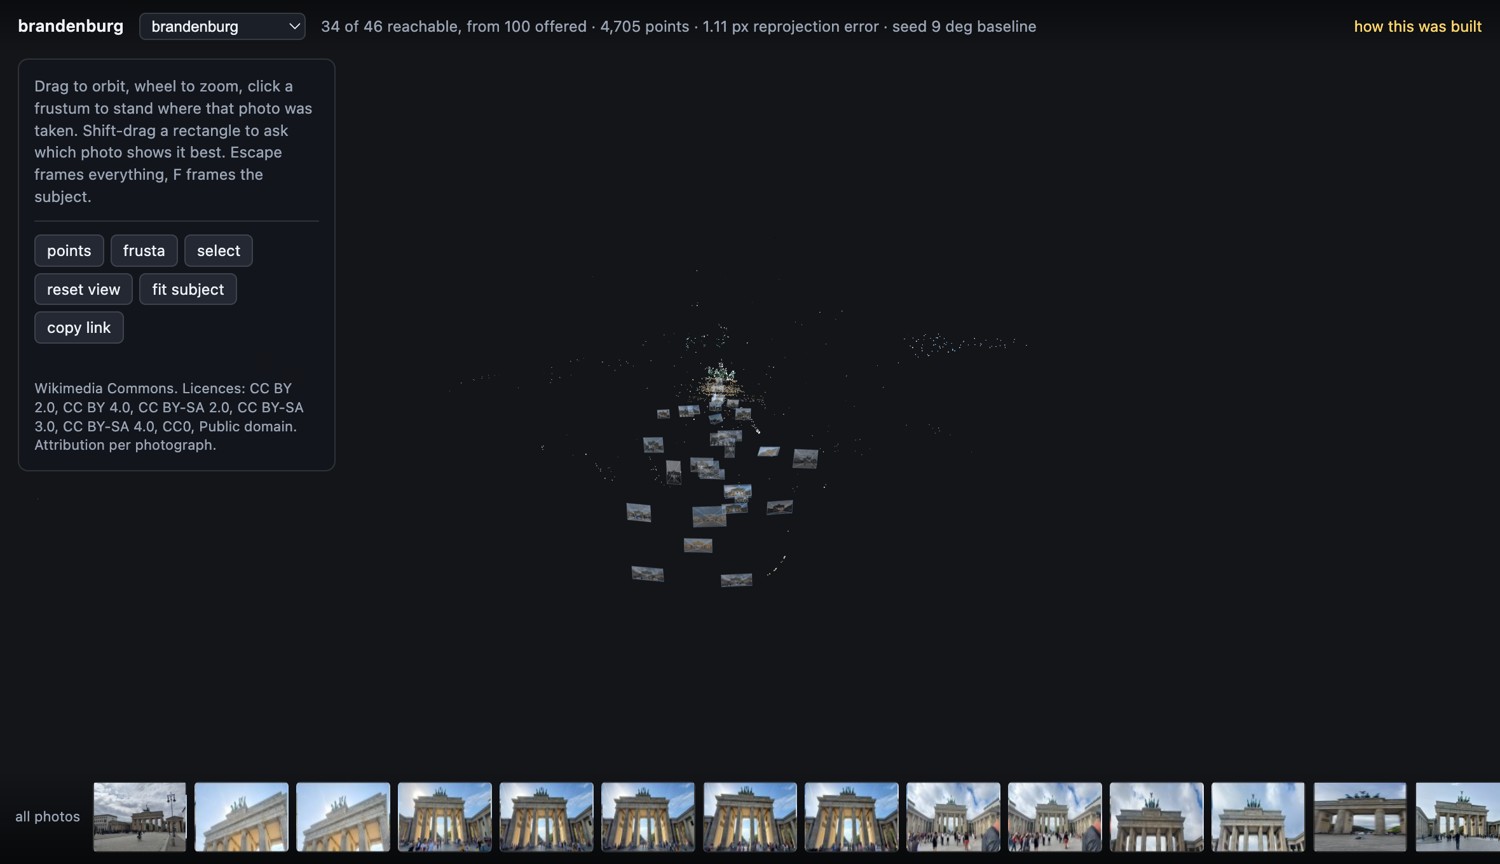
The same moves are available here, on a reconstruction built for this book (Figure 28.5.4). The point cloud and the frusta come out of a from-scratch implementation of the pipeline above: SIFT matches, a fundamental matrix fit by RANSAC per pair, then cameras added one at a time and bundle adjusted, run over a hundred photographs of the Brandenburg Gate collected from Wikimedia Commons. Forty-three of the hundred end up in the reconstruction, and the shortfall has to be read correctly, because it is mostly not a failure of the solver. Eighteen of the photographs match nothing at all, and the verified-match graph breaks into six components, so the largest component supplied forty-six candidates for this reconstruction; forty-three of those forty-six then register. With those correspondences fixed, a disconnected component cannot be aligned by bundle adjustment alone. Additional matching, metadata, or external correspondences could connect it. This run illustrates how matching and connectivity can limit coverage before optimization begins.
28.5.3 Lineage⧉
Photo Tourism opened a research line that scaled the same idea up and hardened it into standard infrastructure. Building Rome in a Day (Agarwal et al. 2009) Agarwal et al. 2009 took the machinery to city scale: reconstructing whole cities from hundreds of thousands of internet photos by parallelizing the matching and reconstruction across a cluster and being clever about which of the quadratically-many image pairs are even worth attempting to match. The matching graph, not the optimization, is the bottleneck at that scale, and much of the work is about pruning it.
The reconstruction machinery itself matured into a community standard: COLMAP (Schönberger & Frahm 2016) Schönberger & Frahm 2016 is the modern incremental-SfM (and multi-view-stereo) tool that most of the field now builds on, the spiritual successor to Snavely's original Bundler. When today's neural-rendering methods (NeRF and its descendants) need to know where each training photo's camera was, they often use COLMAP poses, although alternative SfM systems, calibrated capture, and joint pose-estimation methods also exist. So the data-driven, crowd-sourced reconstruction idea that Photo Tourism introduced did not just survive; it became the quiet pose-estimation substrate underneath a whole generation of 3-D and view-synthesis work (Part 36, 3D and depth).
An unstructured pile of data can substitute for a calibrated instrument, given enough of it and the right geometry to tie it together. Photo Tourism never asks anyone to capture a dataset; it discovers the structure latent in photos taken for entirely unrelated reasons, recovering both the scene and the act of photographing it. That is the recurring wager of this whole part (the data is the prior, the collection is the model), here turned into geometry: the crowd's snapshots, no two alike, are collectively a 3-D scanner. What makes it work is robust matching plus joint optimization, not a clever new feature or a bigger network: RANSAC to survive the flood of wrong correspondences, bundle adjustment to keep thousands of cameras mutually consistent. Scale creates the mess; robustness and a global solve turn the mess back into structure.
Recap: big lessons of this chapter
An unstructured pile of data can substitute for a calibrated instrument, given enough of it and the right geometry to tie it together. Photo Tourism never asks anyone to capture a dataset; it discovers the structure latent in photos taken for entirely unrelated reasons, recovering both the scene and the act of photographing it. That is the recurring wager of this whole part (the data is the prior, the collection is the model), here turned into geometry: the crowd's snapshots, no two alike, are collectively a 3-D scanner. What makes it work is robust matching plus joint optimization, not a clever new feature or a bigger network: RANSAC to survive the flood of wrong correspondences, bundle adjustment to keep thousands of cameras mutually consistent. Scale creates the mess; robustness and a global solve turn the mess back into structure.