2.8 Noise, signal-to-noise ratio and dynamic range⧉
Noise earns a chapter of its own because, more than resolution or optics, noise is what ultimately limits our ability to measure and reconstruct an image. Almost everything else in this book (denoising, demosaicking, deblurring, HDR merging, depth from stereo, super-resolution) is at bottom an attempt to recover a clean signal from noisy measurements, and their performance is limited by how much noise corrupts the input. So understanding where noise comes from, how it scales with light, and which kind dominates when is not a side topic: it is the quiet constraint behind the whole field. It tells you what is recoverable and what is lost for good, how many photons or frames you need to reach a target quality, and, when a result disappoints, whether you are limited by your algorithm or by the physics of the measurement itself. Read this chapter as the floor under every later one.
2.8.1 Noise sources⧉
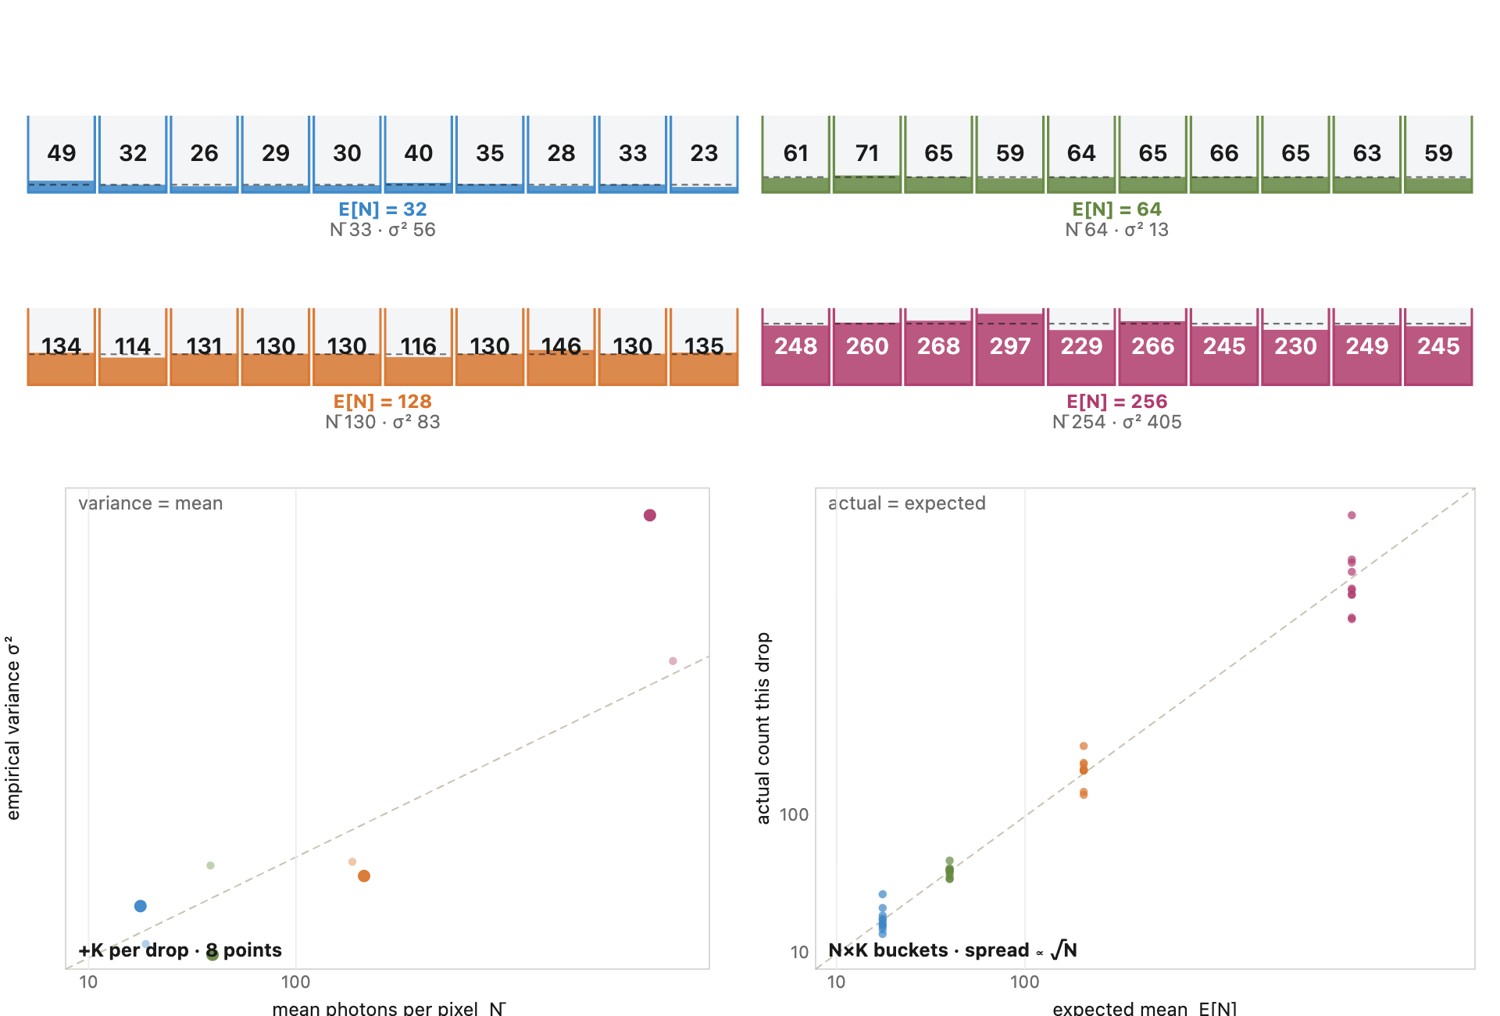
Counting photons is what makes a sensor linear, but counting is also where noise comes from. Take two photos of the same still scene at the same settings and they are not byte-for-byte identical; each pixel value jitters from frame to frame. Several physical sources contribute, and when their fluctuations are independent, their variances add, so to combine them we add variances ($\sigma^2$), not standard deviations (Figure 2.8.3).
Two numbers describe noise spread, and both exist for a reason. Variance (the mean squared deviation) is the quantity the mathematics wants: it is additive for independent sources, exactly what we just used, and the basis of the $1/\sqrt N$ averaging law in Part 13, Denoising; it is the second moment that falls out of every Gaussian and least-squares derivation, and it composes cleanly under linear operations. But its units are squared (squared gray-levels, squared photons), so it means nothing to the eye. The standard deviation $\sigma$ (its square root) is the one people should read: it is back in the original units, directly comparable to the signal: the "$\sigma$" of error bars and the grain you actually see. Rule of thumb: derive and combine in variance, report in standard deviation.
Photon (shot) noise is the deepest source, and it is not a defect of the sensor: it is the light itself. Light arrives as discrete photons at random times, so the count in a fixed interval fluctuates even from a perfectly steady source. For ordinary photographic illumination, the count is well modeled as Poisson, and the defining property of a Poisson process is that its variance equals its mean (Hasinoff 2012 is the canonical short reference). So if a pixel collects $N$ photons on average, the variance of the count is $N$ and the standard deviation is
This is irreducible: no better sensor can remove it, because it is a property of light, not of electronics. It dominates the midtones and highlights, where $N$ is large. Collecting more light, increasing detection efficiency, or pooling independent measurements improves the signal-to-noise ratio. For example, average $N_f$ independent frames of the same scene and the shot noise drops by $\sqrt{N_f}$: the statistical basis of burst denoising and astrophotography stacking.
A Poisson process is the standard model for events that occur independently and at random, at a steady average rate, with no two at exactly the same instant: raindrops striking a tile, clicks of a Geiger counter, and, for us, photons landing on a pixel. It rests on three assumptions: the counts in non-overlapping intervals are independent; events arrive at a constant mean rate $\lambda$; and the process is memoryless (how long you have already waited says nothing about when the next event comes, so the gaps between events are exponentially distributed). Under these, the number of events in a fixed interval follows the Poisson distribution,
whose single parameter $\lambda$ is both its mean and its variance. That coincidence, $\text{variance} = \text{mean}$, is the whole of shot noise: catch $N$ photons on average and the count wobbles with standard deviation $\sqrt{N}$, so the noise grows as the square root of the signal and can never be zero. (Ideal laser light is exactly Poisson; thermal light bunches very slightly above it, but for photography Poisson is the right model.)
Even a flawless sensor is noisy, because light itself is grainy: photons arrive as discrete, randomly-timed events, so the count in any fixed interval follows Poisson statistics ($\sigma=\sqrt N$), and no electronics can remove it: the randomness is in the light, not the chip. The only true cure is collecting more photons: a bigger pixel, a wider aperture, a longer exposure, or averaging many frames. Raising ISO is not a cure: it is gain applied after capture, amplifying signal and shot noise together. This irreducible floor is why bigger sensors win, why shadows are noisy, and what every denoiser later in the book is ultimately fighting.
The remaining sources are added by the hardware:
- Read noise is added by the amplifier and the analog-to-digital converter (ADC) at readout. It is signal-independent (a roughly fixed amount regardless of brightness), so it dominates the shadows (where the signal is tiny) and sets the sensor's noise floor.
- Thermal (dark-current) noise comes from electrons freed by heat rather than light. It is independent of the scene but grows with exposure time and temperature, which is why long exposures and astrophotography call for sensor cooling and dark-frame subtraction. A dark frame, taken with the shutter closed at the same exposure time and temperature, records the mean dark signal and its fixed pattern, hot pixels included, and subtracting it removes those. It does not remove the random part: the dark current's own shot noise in the light frame is a different random draw, and subtracting a single dark frame adds that frame's noise on top, which is why a master dark is averaged from many.
- Fixed-pattern noise is per-pixel non-uniformity: slightly different gain or offset at each photosite, plus hot or stuck pixels. Because it is structured rather than random (the same pattern in every frame), it reads as worse than random noise of the same magnitude, and it is removed by calibration rather than by averaging.
- Row and column noise, and banding. The readout electronics are shared along a row or a column, so their own fluctuation is common to every pixel that shares them: a whole line reads slightly high or slightly low. The result is horizontal or vertical striping, worst in deep shadows and at high gain, and it is correlated along the line, which is what makes it disproportionately visible and what defeats a denoiser. Most of the denoisers in the denoising part assume noise that is independent from pixel to pixel, or at least uncorrelated at the scale they filter; banding is not, so a filter tuned to the per-pixel noise level leaves the stripes largely untouched while smoothing everything else, and the stripes then stand out more than before. The methods that model correlated noise are the exception, and they have to be told its structure. The remedies are their own operations: subtract a per-row and per-column offset estimated from masked pixels at the edge of the sensor (optical black), or estimate it from the image itself in flat regions. Some sensors band worse in particular ISO ranges, which is a hardware fact a pipeline has to know about that sensor.
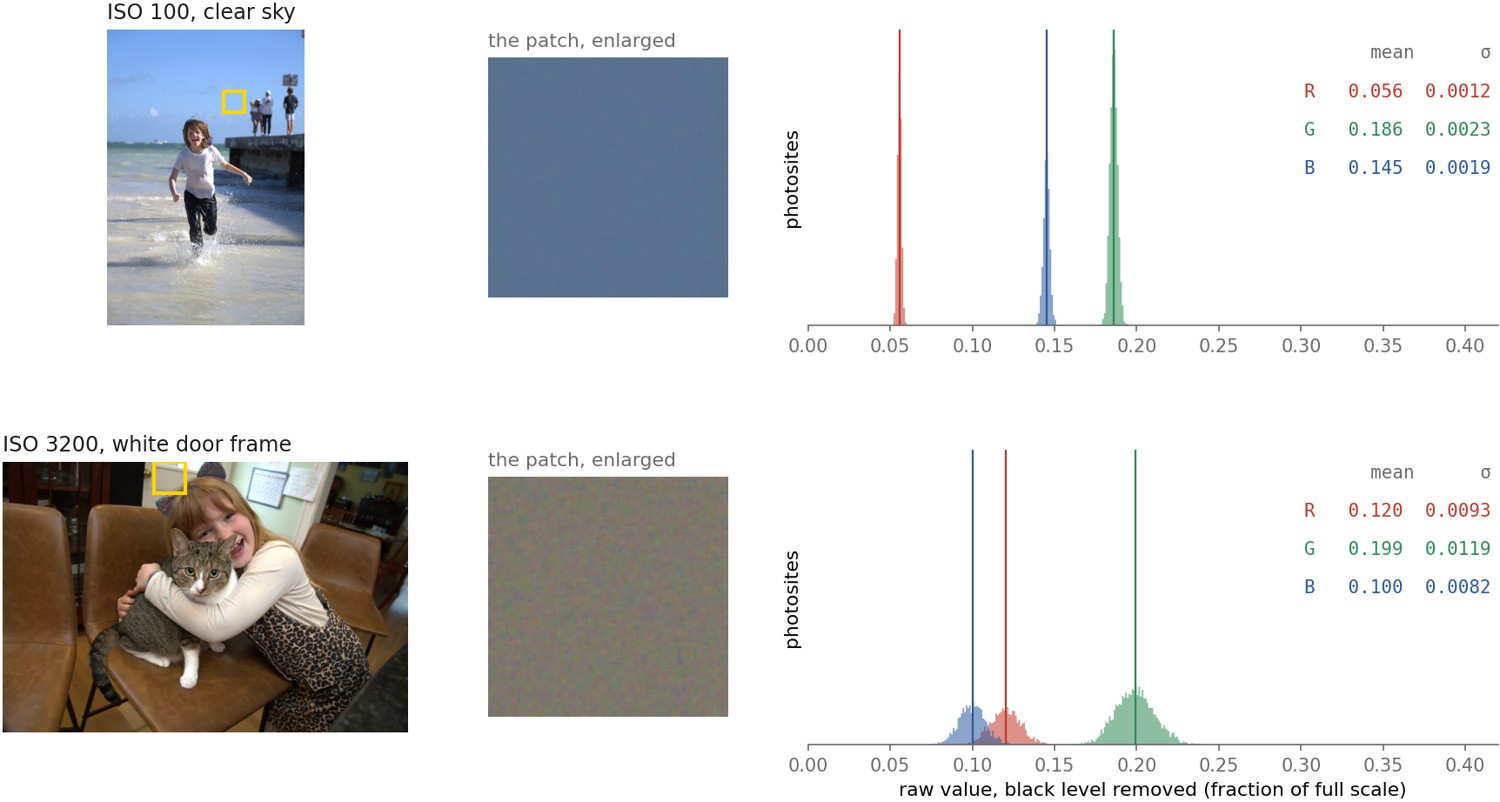
Sensor noise is a sum of distinct sources whose variances add, but each rules a different regime, so diagnosing a noisy image means asking which one you are seeing. Photon shot noise ($\propto\sqrt{\text{signal}}$) dominates the midtones and highlights, and any well-lit shot. Read noise is signal-independent and dominates the deep shadows and short exposures, setting the floor. Thermal / dark-current noise grows with exposure time and temperature: the long-exposure and astrophotography enemy. Quantization matters only with too few bits L2.47. And fixed-pattern noise / PRNU (static per-pixel gain and offset variation) reads as a structured pattern and is removed by calibration (dark and flat fields). Match the symptom to the source before reaching for a fix.
The same five sources, as a reference table (what each varies with, where it dominates, and whether you can remove it):
| source | what it is | varies with | dominant regime | removable? |
|---|---|---|---|---|
| photon (shot) noise | Poisson statistics of photon arrival | $\sigma=\sqrt{N}$, grows as √(signal) | midtones & highlights; every well-lit shot | no (fundamental: only more light helps) |
| read noise | amplifier + ADC at read-out | constant per read-out; relatively lower at higher analog ISO | deep shadows, short exposures (sets the floor) | no, but minimized; charge-binning pays it once |
| dark-current (thermal) | electrons freed by heat | exposure time × temperature (≈ doubles per ~6–8 °C) | long exposures, hot sensors, astro | partly: cooling + dark-frame subtraction |
| quantization | finite ADC bit depth | number of bits (negligible with enough) | only with too few bits / a heavy push | more bits at capture reduce it; dithering decorrelates the error but cannot recover lost precision |
| fixed-pattern / PRNU | per-pixel gain & offset variation, hot pixels | static (same each frame); gain part scales with signal | structured pattern, visible in flats/darks | yes: flat- & dark-field calibration |
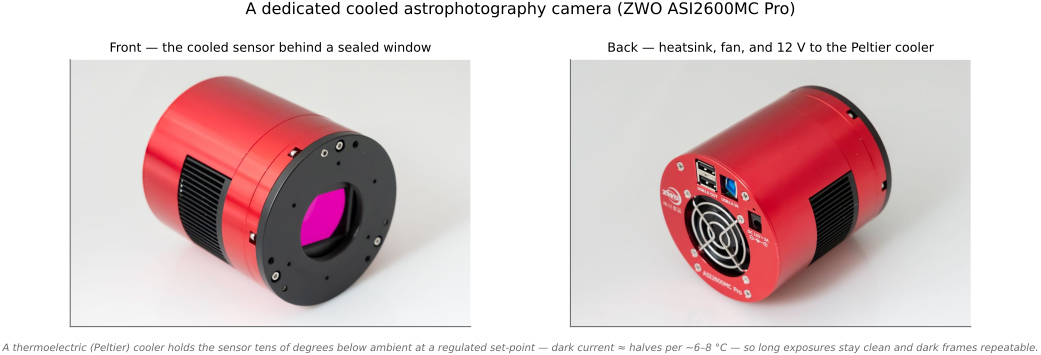
Dark current is the one noise source you can attack with a refrigerator. Because thermally-freed electrons roughly double for every ~6–8 °C, cooling the sensor a few tens of degrees below ambient cuts dark-current noise by a large factor, which is why dedicated astrophotography cameras bolt a thermoelectric (Peltier) cooler to the sensor and run it at a regulated set-point (say −10 °C or −20 °C). The set-point matters as much as the cooling: holding a fixed temperature makes the dark frames repeatable, so a library of master darks taken once can be subtracted from every light frame to remove both the dark-current pedestal and the hot pixels. Combined with the $1/\sqrt N$ stacking of many long sub-exposures (a later chapter), regulated cooling is what lets amateurs pull faint galaxies out of the noise over a night of integration (Figure 2.8.2).
A Peltier cooler is a solid-state heat pump: no moving parts, no refrigerant, no compressor, just a current through a sandwich of semiconductors. Drive a direct current across a junction of two different conductors and heat is carried with it, absorbed on one face and released on the other (the Peltier effect, the mirror image of the Seebeck effect that turns a temperature difference into a voltage in a thermocouple). A practical module wires many small n-type and p-type semiconductor pillars electrically in series but thermally in parallel, packed between two thin ceramic plates; the charge carriers ferry thermal energy all the same way, so one plate goes cold and the other hot, and reversing the current swaps them. The catch is that it does not remove heat, it moves it, and it adds its own electrical power as extra heat on the hot side, so that face must be bonded to a finned heatsink and fan (the back of the camera in Figure 2.8.2); if the hot side is not cleared, the cold side warms right back up. Efficiency is modest, which is why Peltiers suit a small, well-insulated load like a sensor rather than a whole room, but their electrically-regulated set-point (hold the current and you hold the temperature) is exactly what repeatable dark frames need.
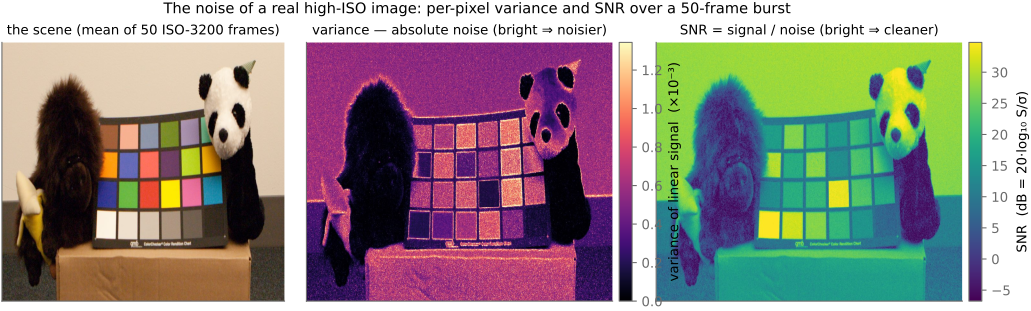
We can see that noise directly. Shoot a burst of one static scene at high ISO and take, for every pixel, its variance across the frames: the result is a map of the noise itself, laid over the picture (Figure 2.8.4). The noise is not uniform: it is heavier in the brighter regions (shot noise) with the brightness dependence predicted by shot noise. Extra variance along edges can instead reveal camera motion, imperfect registration, or illumination changes; these must be excluded when measuring sensor noise.
2.8.2 The algebra of noise⧉
For independent sources, variances add: the single most useful fact for reasoning about noise, and worth turning into a tool. For $N$ independent measurements each of variance $\sigma^2$, the sum has variance $N\sigma^2$ (standard deviation $\sqrt N\,\sigma$), while the average has variance $\sigma^2/N$ (standard deviation $\sigma/\sqrt N$). That $1/\sqrt N$ is the engine of all averaging-based denoising (a whole chapter later). More generally, $\operatorname{Var}(\sum_i w_iX_i)=\sum_i w_i^2\operatorname{Var}(X_i)+2\sum_{i<j}w_iw_j\operatorname{Cov}(X_i,X_j)$. Shared banding and fixed patterns therefore do not follow the independent-frame averaging law. The same algebra settles a subtler, very practical question: is it better to measure light with one big pixel, or with several small ones and add them up?
For this comparison, assume the same quantum efficiency and the same read-noise variance per read, and count detected photoelectrons as $N$. Take a patch that collects $N$ of them. Capture it with one big pixel: it counts $N$ photons (shot variance $N$, since Poisson variance $=$ mean) and adds the read noise once, $\sigma_r^2$. Now split the same patch into four small pixels, each catching $N/4$ photons. Summing their four readings recovers the signal $N$, and the shot noise is identical: the four shot variances $N/4$ add back to $N$, exactly the big pixel's. But each small pixel contributes its own read noise, so the sum carries $4\sigma_r^2$: the read noise is paid four times over. So, provided no light is lost in the gaps between photosites, the big pixel's only real advantage is read noise, not shot noise. Shot noise depends solely on how many photons you caught, never on how you diced up the sensor; read noise is charged once per read-out.
This is exactly why binning matters, and why how you bin matters. Charge binning (pooling the pixels' charge in the analog domain before it reaches the amplifier and ADC) reads the combined charge once, paying read noise a single time and recovering the full big-pixel advantage; some sensors provide this operation, while others combine after separate reads. A quad-Bayer color-filter layout alone does not establish which operation is used. Digital binning (reading the four pixels separately and adding the numbers afterward) pays read noise four times and captures only the shot-noise equivalence. The gap is invisible in bright light (shot-noise-dominated) and decisive in the dark (read-noise-dominated). It also previews the affine model $\sigma^2 = g\,I + \sigma_r^2$ (developed shortly) from a new angle: aggregating $k$ measurements multiplies the read-noise term's contribution by $k$ unless you combine before read-out.
Add the readings of $k$ small pixels and you get the same Poisson (shot) noise as one big super-pixel that caught the same photons, but you pay the read noise $k$ times, once per read-out, instead of once. So the only fundamental advantage of a bigger pixel (or one longer exposure) over many smaller ones is the read noise, not the photon statistics, as long as no light is lost in the gaps. The same holds for aggregating along any dimension: summing $k$ short exposures, or $k$ burst frames, keeps the shot noise of the total light but charges read noise $k$ times. This is precisely why charge-domain binning (combine, then read once) beats digital summation (read $k$ times, then add) in the dark.
2.8.3 Signal-to-noise ratio: it's about ratios⧉
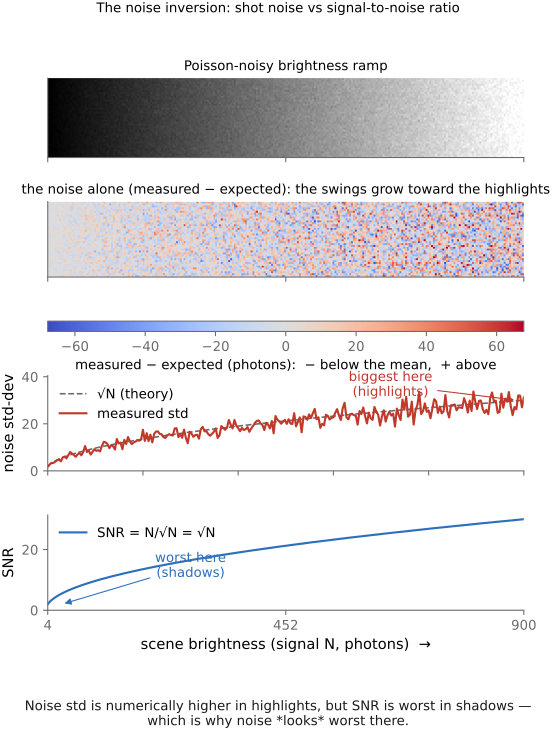
A counterintuitive fact ties the whole part together. Since shot noise is $\sigma = \sqrt{N}$, the absolute noise is actually larger in the bright parts of the image than in the dark parts: a highlight collecting 10,000 photons has $\sigma = 100$, while a shadow collecting 100 photons has only $\sigma = 10$. And yet noise looks worst in the shadows. The resolution is that noise visibility depends strongly on its size relative to the local signal, as well as on display brightness, spatial frequency, and image content. Signal-to-noise ratio (SNR) captures the first of these effects. For shot noise,
The SNR grows with brightness, so it is worst where the light is faintest (the shadows) even though the raw noise magnitude is smallest there (Figure 2.8.6). This emphasis on ratios also motivates gamma and log encoding (log encoding gives equal steps to equal ratios, while a power-law gamma curve approximates perceptual spacing over a useful range) and exactly why exposing to the right works: collecting more photons everywhere, especially in the shadows, raises $N$ and therefore raises the SNR where it is worst.
One caution before we go on, because the acronyms collide: SNR is not PSNR. The signal-to-noise ratio here is a property of a capture, the true signal at a pixel relative to the sensor's noise there ($\sqrt N$ for shot noise), and it answers how clean is this measurement? Peak signal-to-noise ratio (PSNR), which you meet whenever an algorithm is evaluated, is a different animal: a full-reference quality metric that compares a processed image $\hat I$ against a ground-truth reference $I$, computed from their mean-squared error as
where $\mathrm{peak}$ is the largest possible value (e.g. often 1.0 for us when using floating point values, or 255 for 8-bit) and $\mathrm{MSE}=\tfrac1n\sum(\hat I-I)^2$. So SNR describes a photograph (how much noise a single measurement carries, with no reference needed), while PSNR scores a reconstruction against a known truth (how close a denoiser or codec got). Both compare a signal scale to an error scale, but their numerators and purposes differ. PSNR uses a fixed peak rather than the local signal. Maximizing expected PSNR through minimizing MSE favors a conditional-mean estimate, which can blur uncertain detail; that makes it useful for some comparisons but incomplete as a perceptual score.
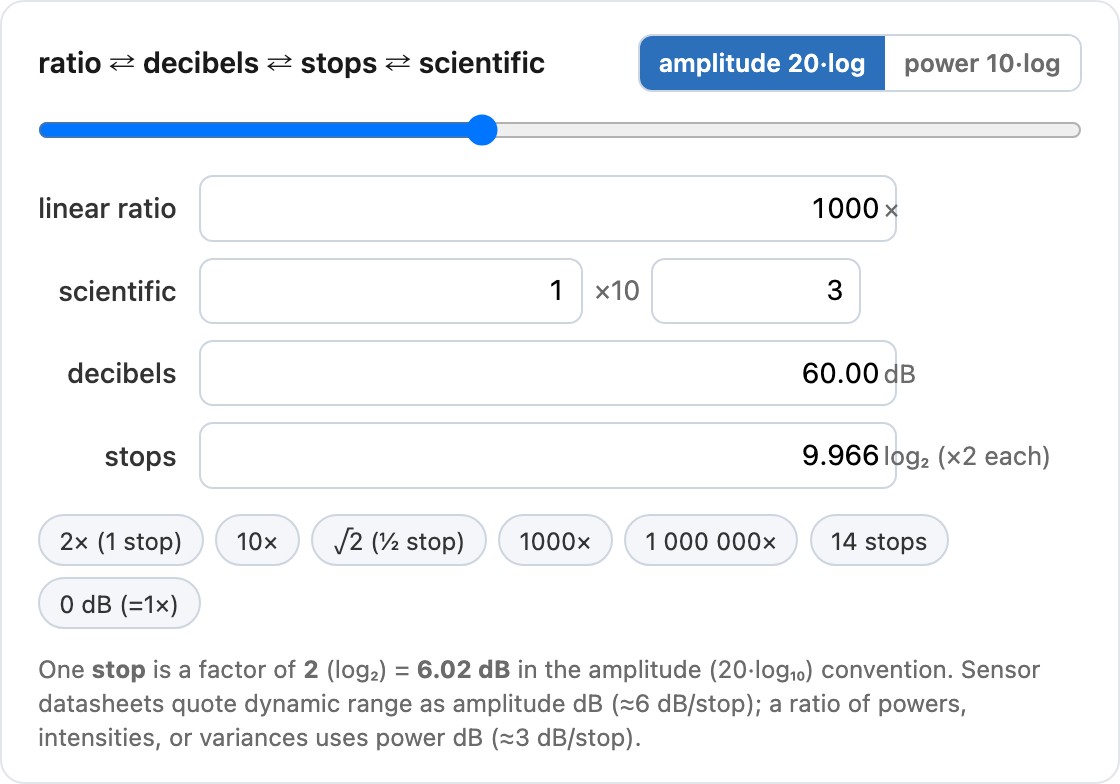
A word on the decibel itself, since it recurs through this chapter and the next. A decibel is just a logarithmic way to write a ratio: for a power (or energy, intensity, variance) ratio it is $10\log_{10}$, and for an amplitude (or voltage, signal) ratio it is $20\log_{10}$, the factor of two coming from power $\propto$ amplitude$^2$. Photographers count the same ratios in stops, factors of two ($\log_2$), so one stop is about 6 dB of amplitude or 3 dB of power. Decibels, stops, plain linear ratios, and scientific notation are thus four scales for the same underlying number, a multiplicative factor, and it helps to move fluently between them (Figure 2.8.5).
Shot noise is Poisson, so its variance grows linearly with the signal ($\sigma^2 \propto N$) and its standard deviation grows only as the square root ($\sigma \propto \sqrt{N}$). Two consequences pull in opposite directions: the absolute noise is larger in highlights than in shadows (a 10,000-photon highlight has $\sigma=100$; a 100-photon shadow has $\sigma=10$), yet the SNR $= N/\sqrt{N} = \sqrt{N}$ is higher in the highlights: the signal outgrows the noise. So bright areas are noisier in absolute terms but cleaner to the eye; the shadows have the worst SNR (Figure 2.8.4, Figure 2.8.6). This is why exposing to the right and brighter scenes look smoother, and why we gamma/log-encode so equal ratios get equal steps.
The affine model, whose full story is the next section, settles a lot of everyday "will this help my noise?" questions at a glance. Read each move against $\sigma^2 = g\,I + \sigma_r^2$ (signal $I$, photon-gain slope $g$, read-noise floor $\sigma_r$), tracking what happens to the signal, the noise $\sigma$, and their ratio. The entries below are for the shot-noise-dominated regime (well-lit midtones); the read-noise term $\sigma_r$ changes only the two rows that mention it.
| scenario | signal | noise $\sigma$ | SNR | what is really going on |
|---|---|---|---|---|
| raise ISO by 1 stop (×2 analog gain) | ×2 | ×2 | ≈ same | amplifies signal and noise together and adds no photons. Read noise, applied after the gain, shrinks relative to the signal, so deep shadows come out a touch cleaner. Not a substitute for light. |
| brighten by 1 EV in software (×2) | ×2 | ×2 | unchanged | multiplies values already recorded, so it amplifies the noise baked in at capture. No shadow benefit, unlike raising ISO at capture. |
| darken by 1 EV in software (×½) | ×½ | ×½ | unchanged | pure scaling; the ratio is untouched (though it can still clip or quantize). |
| average $N$ frames | ×1 | ÷$\sqrt N$ | ×$\sqrt N$ | independent noise partly cancels while the signal stays: the $1/\sqrt N$ law behind burst denoising and stacking. |
| sum $N$ values | ×$N$ | ×$\sqrt N$ | ×$\sqrt N$ | variances add, so SNR grows just like averaging; but read noise is paid $N$ times if the values are read separately. |
| charge-bin $N$ pixels (combine, then read once) | ×$N$ | ×$\sqrt N$ | ×$\sqrt N$, cleaner shadows | same shot noise as a digital sum, but read noise is paid once, not $N$ times. Check that the sensor actually combines charge before separate readout. |
| gather 2× the light (wider aperture or longer exposure) | ×2 | ×$\sqrt 2$ | ×$\sqrt 2$ | collects more photons per measurement, improving SNR before any reconstruction. Read noise unchanged. |
Software rescaling preserves SNR. Analog gain can reduce the relative contribution of noise added downstream, as the ISO section explains. Combining $N$ equally exposed independent measurements improves SNR as $\sqrt N$, while more photons per measurement improve the capture itself.
2.8.4 Noise variance is mostly affine in pixel brightness⧉
Because the variances of these sources add, and because the dominant two scale so simply with the signal, the whole noise level follows a strikingly simple rule that we can measure directly from data.
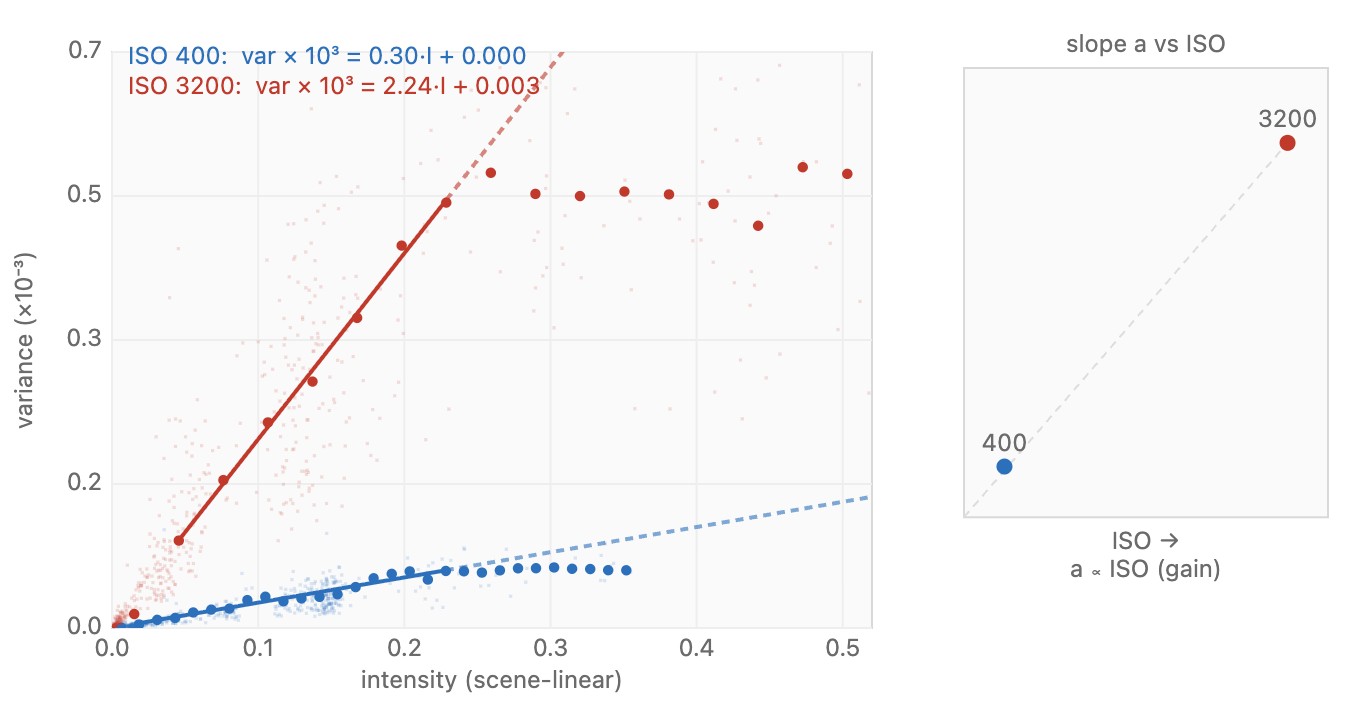
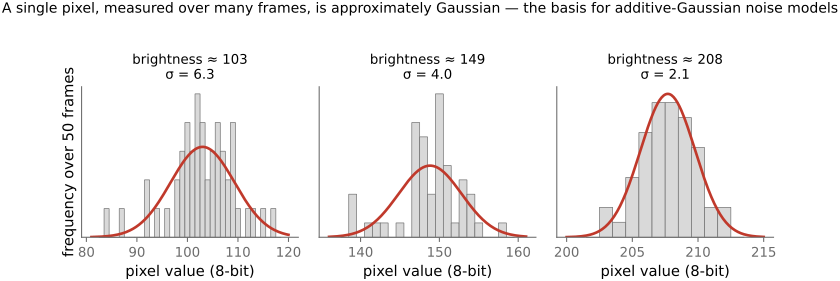
The variances add, and two terms dominate: shot noise contributes an amount proportional to the signal (Poisson, variance = mean, scaled by the gain) and read noise a constant floor. So the total is variance ≈ gain·signal + read², a straight line in brightness (Figure 2.8.7). The slope is the photon gain (it steepens with ISO, which amplifies the signal and its shot noise together); the intercept is the read-noise floor. We can measure it without any model: take an aligned burst of a static scene and, per pixel, plot the variance across frames against the mean. This affine law is a statement about the variance and is essentially exact for the two dominant sources; it says nothing yet about the shape of the distribution. Where the electron count is large, a single pixel's value over many frames does look ≈ Gaussian (Figure 2.8.8), which licenses modeling per-pixel noise as additive Gaussian in the midtones and highlights. That bell is only an approximation, though: the shot term is really Poisson (variance = mean, but discrete, skewed, and non-negative), and in the deep shadows, where only a handful of electrons land, it stops looking Gaussian at all. The additive-Gaussian model is a convenience of the well-exposed regime, not a law of noise in general (we pin down where it breaks below).
 Carl Friedrich Gauss (1777–1855), the "prince of mathematicians," appears repeatedly in this book, and you have just met him in the bell curve. The Gaussian (normal) distribution that a noisy pixel traces over many frames is his, and so is least squares, which he used in 1801 to recover the orbit of the dwarf planet Ceres from a handful of sightings and which underlies nearly every fit and reconstruction we do. The same name returns as the Gaussian blur, Gaussian elimination inside our linear solvers, and the Gauss–Seidel iteration. That a sum of many small independent effects collapses into one bell shape (the central limit theorem) is exactly why the additive-Gaussian noise model keeps working. Portrait: painting by Christian Albrecht Jensen, 1840, public domain (via Wikimedia Commons).
Read the affine model the other way and it becomes a simplified noise simulator: the quickest way to turn a clean image into realistic noisy data, for stress-testing a denoiser or building the synthetic training pairs this book leans on (Chapter 7.3, Deep learning). Two rules make or break it. First, work on a linear image, never a gamma-encoded one: variance is affine in brightness only in linear light, so noise added after the tone curve injects the wrong amount in the shadows, exactly where it shows, and looks plainly fake. Second, and less often stated, do the physics in the sensor's native unit, electrons (photon counts), because that is the only unit in which shot noise is exactly Poisson. So convert the linear image to a mean electron count, draw the shot term as a Poisson variate and the read term as a Gaussian, then carry the result back out through gain, black level, clipping, and quantization (Algorithm 2.8.1):
for each linear pixel value I in [0, 1]:      # 1.0 == a full photosite well; NOT gamma-encoded
    N_e   = I * full_well                     # to ELECTRONS: the photon scale
    shot  = poisson(mean = N_e)               # shot noise IS a Poisson count  (var = mean, sigma = sqrt(N))
    shot  = min(shot, full_well)              # clip 1: the well saturates (electrons), BEFORE read-out
    e     = shot + gaussian(0, read_noise_e)  # read/constant noise: zero-mean Gaussian, in electrons
    DN    = round(e * gain + black_level)      # to code values: gain folds in ISO; add the pedestal
    DN    = clamp(DN, 0, max_DN)              # clip 2: the ADC rails (highlights at max, floor at 0)
    I_out = (DN - black_level) / (max_DN - black_level)   # linear; may be negative after black subtraction
# apply gamma / the display curve only AFTER this loop, never before
2.8.5 A fuller model of noise: Poisson photon noise plus clipping plus Gaussian electronic noise plus a second clipping⧉
The affine variance model is often paired with a fast distributional approximation: a symmetric Gaussian whose variance rides the affine line $\sigma^2=a\,I+b$. To see exactly where that approximation holds and where it breaks, and to simulate noise faithfully down in the shadows and up at saturation, we now build the full generative model it approximates. It has four stages, applied in the order the sensor applies them: Poisson photon noise, the well's saturation clip, additive Gaussian read noise, and the ADC's second clip. Working in electrons keeps the scales consistent. This remains a model: real read noise can be correlated or non-Gaussian, and real saturation need not be a perfect hard clip. The affine Gaussian follows away from clipping when counts are sufficiently large.
The units are everything. Three of them coexist, and you must keep them straight. The scene-linear image is normalized, values in $[0,1]$ with $1.0$ standing for a full well. The sensor counts in electrons (photons converted at the quantum efficiency $\eta$), and this is where shot noise lives: a mean of $N$ electrons gives a Poisson count whose variance is $N$, so $\sigma=\sqrt N$. The ADC finally reports digital numbers (DN, or ADU: the raw code values), related to electrons by a gain $g$ in DN per electron, into which the ISO setting folds. The one non-negotiable step is the conversion $N=I\cdot N_{\text{full}}$ before the Poisson draw: "variance equals mean" holds only for the count, so drawing Poisson in normalized $[0,1]$ or in DN gets the noise magnitude wrong by whatever the scale factor is. Multiply the clean image up into electrons, add the noise there, and only then scale back. Typical numbers: a full-frame photosite holds $N_{\text{full}}\approx30{,}000$-$60{,}000$ electrons, a phone pixel a few thousand; read noise $\sigma_r$ is $\sim1$-$3\,e^-$ on good CMOS when measured in input-referred electrons, and often falls as analog gain rises until a floor is reached. Pixel design and readout mode matter as much as sensor format.
In electrons the linear (shot) term is not a fitted constant, it is pure physics. Write the normalized linear measurement as $x\in[0,1]$, a fraction of full well. The mean electron count is
with $N_{\text{full}}$ the full-well capacity, the electrons a photosite holds at saturation. Shot noise is Poisson, so its variance in electrons equals that mean:
That is the whole "linear term $a\,x$": a straight line through the origin whose slope is simply the well capacity, with nothing to tune. And the slope is set entirely by physics, by how many photons the exposure delivers and the quantum efficiency $\eta$ that converts them to electrons ($N=\eta\,N_{\text{photons}}$, so $N_{\text{full}}=\eta\,N_{\text{photons at saturation}}$). The normalized slope $a$ of L2.42 looks like a fitted number only because of the change of units: rescaling those electrons back into $[0,1]$ (divide by $N_{\text{full}}$) or into DN (multiply by the gain) turns the clean $N_{\text{full}}\,x$ into $a\,x$. In electrons it is just the photon count.
The affine Gaussian of L2.42 replaces the Poisson draw by a Gaussian with matching mean and variance. The coefficients depend on the units of both the signal and the noise. If the output is divided by full well, then, away from clipping and ignoring quantization,
For example, $N_{\text{full}}=30{,}000$ and $\sigma_r=2$ give $a=3.33\times10^{-5}$ and $b=4.44\times10^{-9}$. A smaller illustrative well of $3{,}000$ electrons with the same read noise gives $a=3.33\times10^{-4}$ and $b=4.44\times10^{-7}$. These are calculated examples, not specifications for a camera class. In black-subtracted DN, with mean $\mu=gN$, the variance is instead $g\mu+g^2\sigma_r^2$. If those DN are normalized by a code range $A$, the coefficients become $a=g/A$ and $b=g^2\sigma_r^2/A^2$. A noise profile is meaningless without this normalization convention.
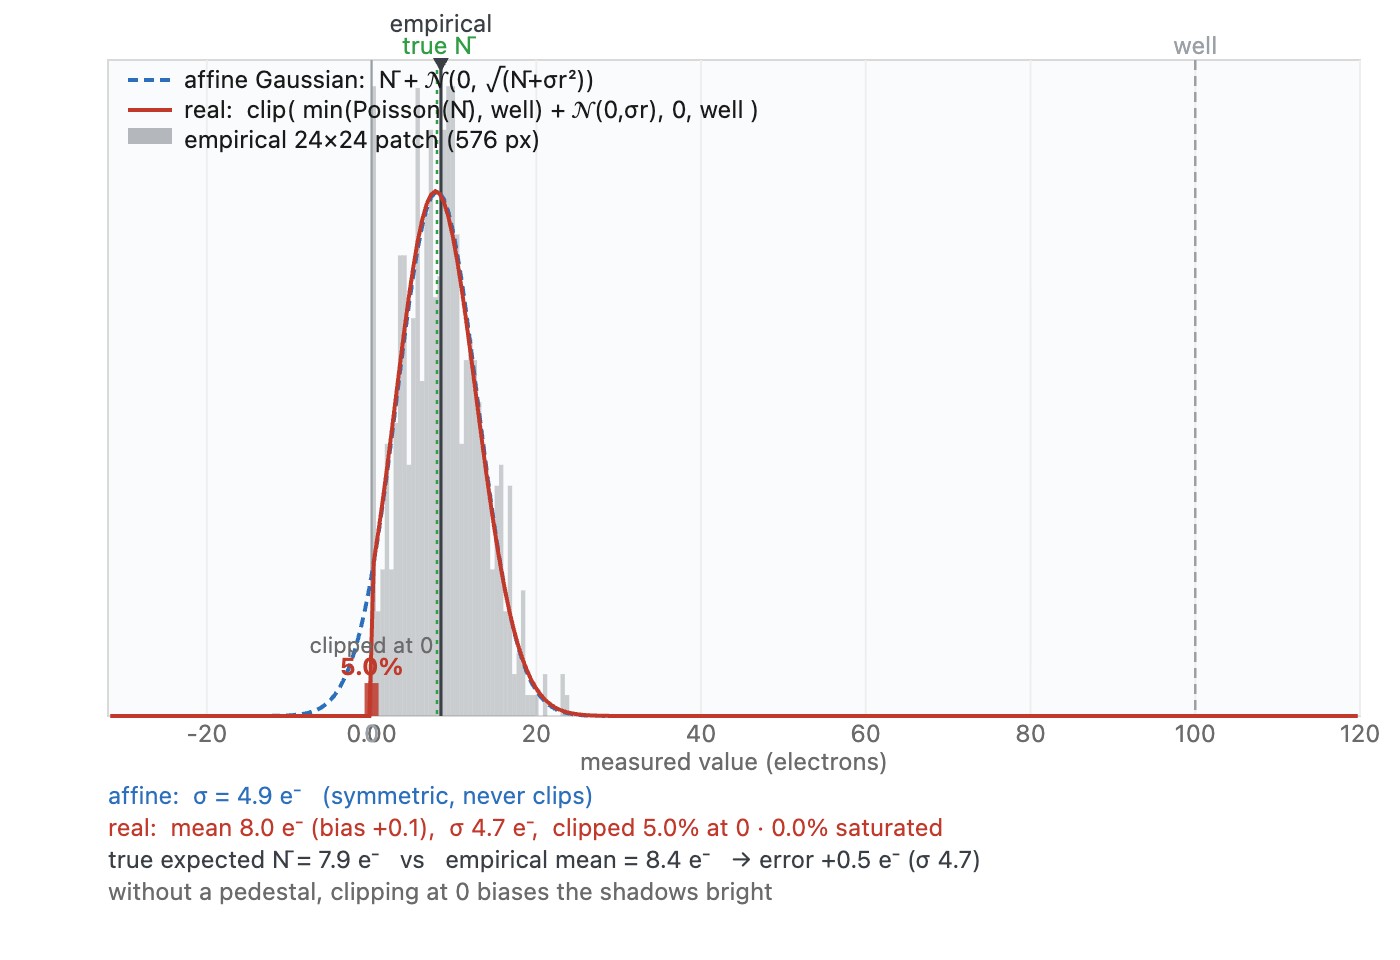
When is that Gaussian good enough, and when does it break? A Poisson count is a sum of many independent tiny arrivals, so by the central limit theorem it approaches a Gaussian of the same mean and variance as the count grows: $\text{Poisson}(N)\approx\mathcal N(N,\,N)$. Its skewness is $1/\sqrt N$, so the bell is nearly symmetric once $N$ is a few dozen, and in midtones and highlights (thousands of electrons) the Gaussian is indistinguishable from the truth and cheaper to draw. It breaks in exactly the place that matters, the deep shadows, where $N$ falls to single digits. Three things go wrong at low counts: the distribution is discrete (you caught 3 photons or 4, never 3.5), it is right-skewed (a tail toward more photons, none toward fewer), and it is non-negative, whereas a Gaussian will hand back negative electron counts, which are unphysical and, once clipped at zero, bias the shadows bright (the truncation of L2.43 below). Rule of thumb: use the true Poisson draw below a couple of dozen electrons and the Gaussian above; a simulator that wants faithful shadows, or that models the low-light or photon-counting regime at all, must use Poisson. A Gaussian approximation can be faster, but the benefit depends on the sampler and hardware, and a threshold near $N\approx20$ still introduces approximation error. Test the distribution and runtime for the application; an exact Poisson sampler is a straightforward default.
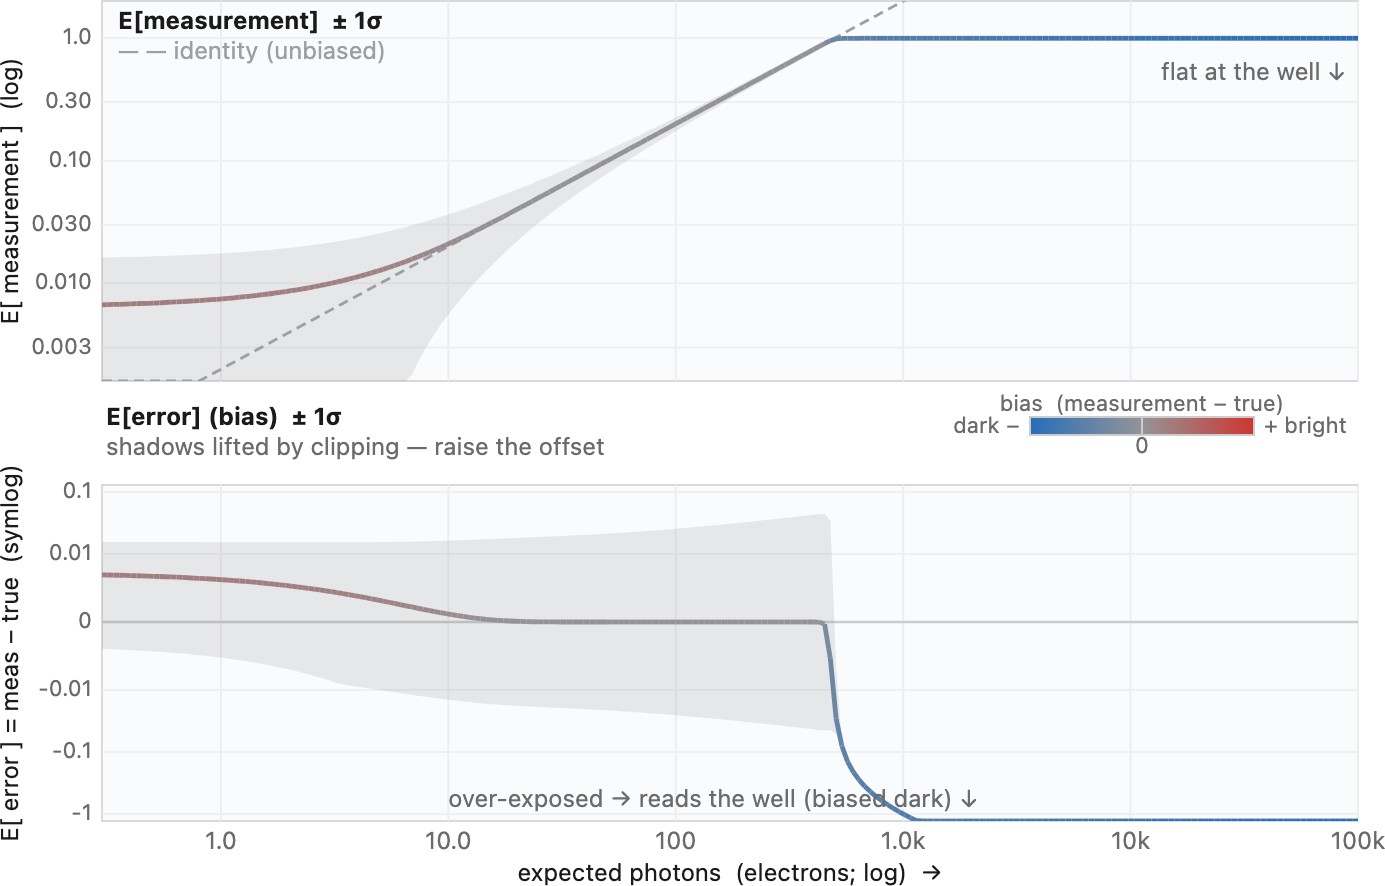
How far from zero-mean is the noise? We lean everywhere on the assumption that noise averages out: that a measurement is right on average even when any single frame is off, since that is exactly what lets a burst average or a denoiser recover the truth. How well does that hold? Two of the effects just discussed pull in opposite directions. For shot noise alone the answer is: it is unbiased, exactly. A Poisson count satisfies $\mathbb{E}[\text{Poisson}(N)] = N$, so despite its right skew the expectation sits precisely on the true signal, and averaging many frames converges to it with no offset. The asymmetry is a fact about the shape of a single draw, not a bias in its mean; this is why a simple frame average is still the right estimator in the shadows even where the distribution is visibly lopsided. Clipping is what actually breaks zero-mean. At the black rail the recorded value cannot go below zero, so the negative half of the read noise is chopped off and the average is pushed up: for a signal sitting right on the floor with read-noise $\sigma_r$, the lift is about $\sigma_r/\sqrt{2\pi}\approx 0.4\,\sigma_r$ (a few tenths of an electron), decaying to nothing once the signal climbs a couple of $\sigma_r$ above zero. At the white rail the mirror image drags saturating highlights down. So the noise is zero-mean across the whole midtone range and departs from it near a rail, within a distance set by the noise standard deviation rather than a fixed number of exposure stops (the truncation of L2.43 below). That residual bias is small in electrons but lands where the eye is most critical, which is precisely why sensors add a black-level pedestal: lifting the signal a few hundred codes off zero keeps nearly all of the read-noise distribution measurable at black and makes clipping bias negligible. The pedestal is an offset in the recorded signal, described by metadata: the file must say how much was added, and every reader must subtract it before the numbers mean light. A file that misreports it renders as milk, with no reachable black and a cast the color of whichever channel's pedestal was largest; Chapter 8.2, What the numbers mean dissects a real case from this book's own raw developer, with the two renders side by side.
The model in one place. All the pieces now assemble into a single forward model whose operations happen in a definite order that a careless simulator scrambles. With $x\in[0,1]$ the normalized linear signal, $N_{\text{full}}$ the well capacity, $\sigma_r$ the read noise in electrons, $g$ the gain in DN per electron, $B$ the black-level pedestal, and $\mathrm{DN}_{\max}$ the ADC ceiling, the recorded value is built up as
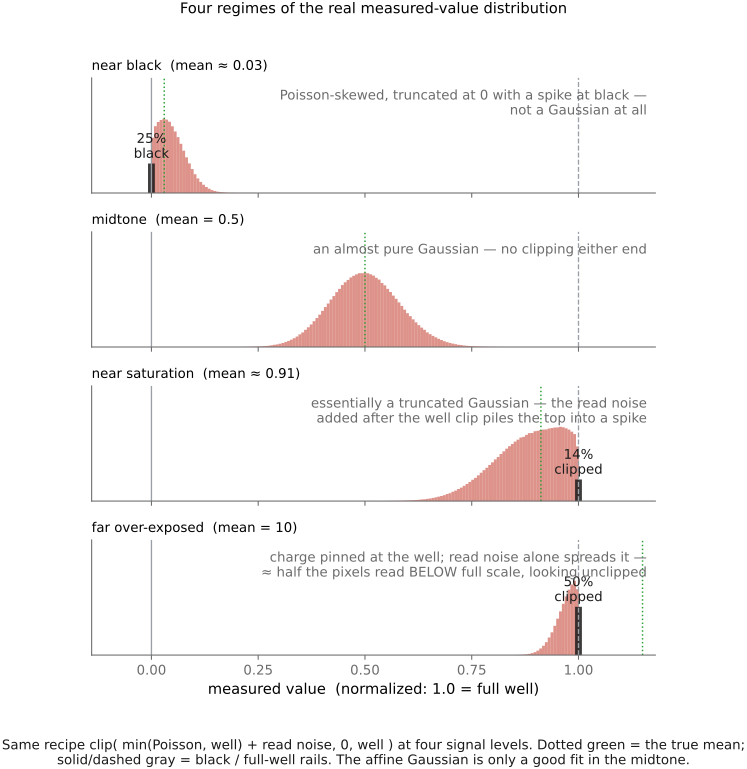
Two choices are not interchangeable, as stressed above: the shot term is a discrete, non-negative Poisson count (Gaussian only in the many-electron limit), while the read term is modeled as Gaussian. What the single equation makes unmissable is that there are two clips, at different stages and in this order. Saturation is physical and comes first, in electrons, at the well: once the photosite is full it stops counting, capping $n$ before any read noise is added. The ADC clip comes last, after read noise and gain, and bites at both rails, $\mathrm{DN}_{\max}$ for highlights and $0$ for shadows, the floor being exactly what the pedestal $B$ exists to hold the read-noise bell clear of. The order is not cosmetic: when $gN_{\text{full}}+B$ coincides with the ADC ceiling, read noise added between the two clips produces a spike at $\mathrm{DN}_{\max}$ plus a short skirt below it (positive read excursions clipped away by the ADC, negative ones knocking saturated pixels back down), the very asymmetry the figure below draws. The affine Gaussian of L2.42 drops both clips and the Poisson shape at once, which is why it matches the full model through the midtones and parts from it at each extreme.
A recorded value is clamped to $[0,\text{max}]$. Near black the negative half of the noise is cut off and frames pile up at 0; near white the positive half is. So at the extremes the noise distribution is asymmetric, with its mean pushed inward (Figure 2.8.12). The consequence for denoising: a naive average or smoothing returns that biased mean, so it makes shadows come out too bright and highlights too dark: a bias every denoiser must correct for (we return to it in Denoising, BASIC).
The top rail is not a hard wall. Read noise is added after the charge saturates at the well (clip 1) and before the ADC clamps (clip 2), so a pixel pinned at full well is digitized to $g\,N_{\text{full}}+B$ plus a zero-mean Gaussian excursion: about half of all saturated pixels read strictly below $\mathrm{DN}_{\max}$, by up to a read-noise's worth. It makes no difference how far over-range the pixel truly is: a highlight ten times too bright still only fills the well to $N_{\text{full}}$, gets the same read noise, and lands below the maximum half the time. So a measured value just under the ceiling does not prove a pixel was unsaturated, and a patch of genuinely clipped highlights reads a little spread of values, not one flat number. Anything that must know what saturated (HDR-merge pixel rejection, highlight reconstruction, clipping warnings) has to threshold a few $\sigma_r$ below $\mathrm{DN}_{\max}$, never exactly at it.
A single measured value is built in four stages, in the order the sensor applies them: (1) Poisson photon shot noise, whose variance equals its mean, the irreducible floor; (2) saturation at the well, a hard clip of the electron count at the full-well capacity; (3) additive Gaussian read noise, the electronics' contribution, applied after the charge is held; and (4) the ADC clip to $[0,\mathrm{DN}_{\max}]$, after gain and the black-level pedestal. Do it in electrons, the only unit in which shot noise is exactly Poisson. The tidy affine Gaussian ($\sigma^2=a\,I+b$) is just the well-exposed limit of this recipe with the Poisson shape and both clips dropped, which is why it matches in the midtones and parts from the truth in the deep shadows (skewed, floored) and at saturation (a soft, spread-out ceiling). The order matters: because read noise lands between the two clips, saturated highlights do not pile up as a clean spike (see the two clipping lessons above). Get it right and you reproduce real noise; get it wrong and your simulator, training data, or denoiser is fitting a sensor that does not exist.
Which model should you use? For forward simulation of a raw sensor, the Poisson-plus-read-noise model with the two clips is a useful starting point. It preserves low-count behavior and saturation, and can be extended with dark current, fixed patterns, and correlated readout noise when those matter. The affine Gaussian is useful at higher counts or when an algorithm needs a continuous likelihood. Be careful about its claimed simplicity: a Gaussian with fixed variance has a quadratic negative log-likelihood, but signal-dependent variance does not. For one observation $y$ and unknown clean value $x$, it gives
Both the denominator and the log term depend on $x$. Freezing the variances from an estimate gives weighted least squares, often inside an iterative algorithm. A constant-variance Gaussian is a further approximation, appropriate when a small patch has nearly uniform brightness, after a suitable variance-stabilizing transform, or for a controlled benchmark. Choose the model for the data and the question, and keep its assumptions explicit.
Drawing Poisson noise. In Python, NumPy does it vectorized over the whole image at once, each pixel drawn at its own mean:
import numpy as np
rng = np.random.default_rng()
electrons = rng.poisson(mean_e)   # mean_e: float array of electron counts -> integer counts
In C++, the standard library provides it in <random>; the mean is a construction parameter, so a per-pixel mean means constructing (or re-parameterizing) the distribution for each pixel:
#include <random>
std::mt19937_64 rng(seed);
std::poisson_distribution<long long> shot(mean_e);  // mean_e > 0
long long k = shot(rng);                            // one Poisson electron count
Put together, the whole simulator is short, in Python (NumPy, whole image at once) or C++ (per pixel, standard library only). Pick a tab and copy (Listing 2.8.1):
import numpy as np

def add_sensor_noise(img, full_well=30000.0, read_noise_e=2.0,
                     bit_depth=14, black_level_dn=0.0, rng=None):
    """Physically-based sensor noise on a scene-LINEAR image where 1.0 == full well.

    Everything happens in electrons, the only unit in which shot noise is Poisson.
    Returns a linear float image; black subtraction can produce negative values.
    """
    img = np.asarray(img, dtype=np.float64)
    if not (1 <= bit_depth <= 30) or int(bit_depth) != bit_depth:
        raise ValueError("bit_depth must be an integer from 1 to 30")
    bit_depth = int(bit_depth)
    if not np.isfinite(full_well) or full_well <= 0:
        raise ValueError("full_well must be finite and positive")
    if not np.isfinite(read_noise_e) or read_noise_e < 0:
        raise ValueError("read_noise_e must be finite and nonnegative")
    if not np.all(np.isfinite(img)):
        raise ValueError("image values must be finite")
    rng = np.random.default_rng() if rng is None else rng
    max_dn = float((1 << bit_depth) - 1)
    if not np.isfinite(black_level_dn) or not 0 <= black_level_dn < max_dn:
        raise ValueError("black level must be in [0, max_dn)")
    gain   = (max_dn - black_level_dn) / full_well          # DN per electron

    mean_e    = np.clip(img, 0.0, None) * full_well         # 1. to electrons
    electrons = rng.poisson(mean_e).astype(np.float64)      # 2. shot: Poisson count
    electrons = np.minimum(electrons, full_well)            # 3. clip 1: well saturation (electrons)
    electrons += rng.normal(0.0, read_noise_e, img.shape)   # 4. read: Gaussian, in electrons

    dn = np.round(electrons * gain + black_level_dn)        # 5. to DN: gain + pedestal
    dn = np.clip(dn, 0.0, max_dn)                           # 6. clip 2: the ADC rails
    return (dn - black_level_dn) / (max_dn - black_level_dn)  # 7. linear, retaining sub-black noise
#include <random>
#include <vector>
#include <cstdint>
#include <cmath>
#include <algorithm>
#include <stdexcept>

// Physically-based sensor noise on a scene-LINEAR image where 1.0 == full well.
// Everything happens in electrons, the only unit in which shot noise is Poisson.
// `img` is row-major linear pixels; modified in place. Sub-black noise may be negative.
void add_sensor_noise(std::vector<float>& img,
                      double        full_well      = 30000.0,
                      double        read_noise_e   = 2.0,
                      int           bit_depth      = 14,
                      double        black_level_dn = 0.0,
                      std::uint64_t seed           = 0)
{
    if (bit_depth < 1 || bit_depth > 30 || !std::isfinite(full_well) || full_well <= 0 ||
        !std::isfinite(read_noise_e) || read_noise_e < 0)
        throw std::invalid_argument("invalid sensor parameters");
    for (float px : img)
        if (!std::isfinite(px)) throw std::invalid_argument("nonfinite image value");
    std::mt19937_64 rng(seed);
    std::normal_distribution<double> read(0.0, 1.0);
    const double max_dn = double((1u << bit_depth) - 1u);
    if (!std::isfinite(black_level_dn) || black_level_dn < 0 || black_level_dn >= max_dn)
        throw std::invalid_argument("invalid black level");
    const double gain   = (max_dn - black_level_dn) / full_well;   // DN per electron

    for (float& px : img) {
        double mean_e = std::max(0.0, double(px)) * full_well;     // 1. to electrons
        double e;
        if (mean_e > 0.0) {                                        // 2. shot: Poisson count
            std::poisson_distribution<long long> shot(mean_e);    //    (mean must be > 0)
            e = double(shot(rng));
        } else {
            e = 0.0;
        }
        e = std::min(e, full_well);                              // 3. clip 1: well saturation (electrons)
        e += read_noise_e * read(rng);                                          // 4. read: Gaussian, in electrons
        double dn = std::round(e * gain + black_level_dn);       // 5. to DN: gain + pedestal
        dn = std::min(max_dn, std::max(0.0, dn));                // 6. clip 2: the ADC rails
        px = float((dn - black_level_dn) / (max_dn - black_level_dn)); // 7. linear; may be negative
    }
}
The cardinal mistake is the one-liner everyone reaches for first: a single constant-$\sigma$ Gaussian added to a gamma-encoded image. It is signal-independent (no shot noise) and in the wrong space, so it looks wrong in exactly the shadows where noise matters. Poisson photoelectron counts plus Gaussian read noise provide the baseline model here; sensor-specific effects may require more terms.
To summarize, the affine law gets the variance right, but the Gaussian shape is only an approximation, and it departs from a real sensor in three ways. The first we have already met: in the deep shadows the true statistics are Poisson, not Gaussian. The other two happen at the two extremes, where the recorded value is clipped (the two soft-clipping lessons above, L2.43 and L2.44).
That clipping caveat is the first crack in the affine model; here is a larger one. The law $\sigma^2 \approx a\,I + b$ describes the noise as the sensor hands it over (the raw mosaic, straight off the ADC); it is a fact about the sensor, not about the final photograph. Run that raw through the computational-photography pipeline and the clean affine line bends. A burst merge (align-and-average $N$ frames, Part 13, Denoising) drives the variance toward $1/N$ of a single frame, but unevenly (the robust merge keeps more frames in still regions than near moving edges), so the noise becomes spatially varying, and highlight clipping means it is no longer even affine in brightness. Demosaicking (Part 15, Demosaicking and joint methods) bends it too: an interpolated color is a weighted average of neighboring pixels, and fixed positive averaging weights reduce variance for independent samples. The amount varies across pixels; negative or adaptive weights need not reduce it. Shared input samples also correlate neighboring output errors. After a few ISP stages the tidy 'gain·signal + read²' line is gone, and a downstream algorithm that still assumes it (a plain AWGN denoiser, say) is fitting a model the data no longer obeys.
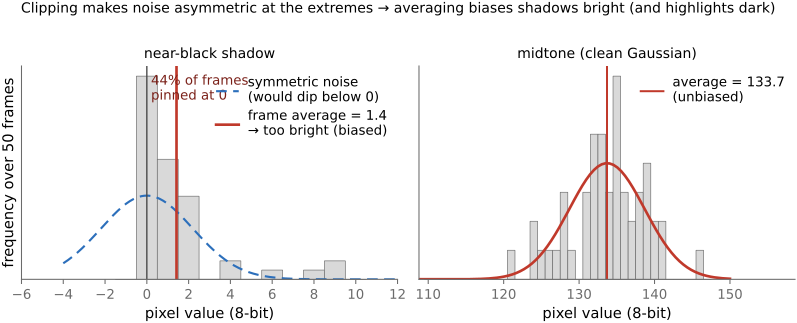
Manufacturers know this and design around it: many sensors deliberately lift the black point before digitizing. They add a fixed offset (a "black level" or bias, a few hundred code values) to the signal, so nearly all of the read-noise distribution, negative excursions included, lands above zero and is recorded rather than clipped (the value depends on the camera, bit depth, channel, and readout mode). For example, the 50-megapixel Sony raws used for this book's figures record black at code 512 and saturation at 16383 on their 14-bit scale, and many 14-bit Canon raws sit near 2048; the file's own black-level tag, which exiftool prints, is the number to trust. The raw file then carries an explicit black-level tag that the converter subtracts back out. Keeping the noise unclipped this way is exactly what lets noise-weighted averaging, flat/dark calibration, and shadow-lifting stay unbiased down in the darkest tones, at the cost of a sliver of headroom. One discipline follows: after subtracting the black level, near-black pixels can legitimately go slightly negative, and that must be preserved, not clamped, all the way until display, or the bias creeps right back in.
Black-level handling must be checked for the actual raw format and camera mode. Some files preserve an offset and describe it in metadata; others have had a black estimate subtracted, sometimes followed by clipping. A reported black value of zero therefore does not by itself prove that no negative noise was lost. Clipping in-camera can make the darkest samples look tidier, but discards the sub-black tail, so subsequent averaging and dark-frame calibration are biased near black. Inspect optical-black samples or dark frames when available, and use a camera-specific calibration if the metadata is missing or inaccurate.
The affine model is also a recipe: it is how you turn a clean image into realistic noisy data: for testing a denoiser, or for the synthetic training pairs this book leans on (→ synthetic data in Chapter 7.3, Deep learning). Work in linear light, think in electrons, and apply the sources in capture order:
- Scale to electrons. Map the clean linear image to a photon count, $N = I\cdot N_{\text{full}}$, or pick an exposure level; fewer electrons means a noisier result. This chooses where on the SNR curve you land.
- Shot noise, then saturation. Replace each pixel by a Poisson draw with mean $N$ (
numpy.random.poisson(N)), or a Gaussian of variance $N$ when $N$ is large: this is the $\sigma=\sqrt N$ floor, signal-dependent and drawn per pixel, not added as a constant. Then cap the count at the well capacity $N_{\text{full}}$ (clip 1: the well saturates, in electrons, before read-out). - Read noise. Add zero-mean Gaussian noise of standard deviation $\sigma_r$ electrons (the floor; larger at higher ISO).
- Gain, black level, clip, quantize. Multiply by the analog/ISO gain, add the black-level offset, clip to the ADC range at both rails (clip 2: the maximum for highlights, $0$ for shadows), and quantize to the bit depth.
- Re-encode. Apply gamma / the camera curve last, so the noise you built in linear light decodes correctly.
The cardinal mistake is adding a single constant-σ Gaussian to a gamma-encoded image: that is neither signal-dependent (no shot noise) nor in the right space, and it looks wrong in exactly the shadows where it matters. Real noise is Poisson + Gaussian, in linear electrons; everything else is a shortcut.
2.8.6 Noise as a function of ISO⧉
The affine constants $a$ and $b$ are not fixed properties of a sensor: they slide with the ISO setting, because an ISO setting can change analog gain, conversion-gain mode, and sometimes digital scaling. Here we first model an analog gain applied partway down the readout chain, and it matters a great deal where each noise source enters relative to that amplifier. Three sources, three positions:
- Photon (shot) noise enters at capture, in electrons, with variance equal to the mean count $N=x\,N_{\text{full}}$. It is then amplified along with the signal.
- Pre-gain read noise $\sigma_{\text{pre}}$ (electrons) is the noise of the photosite and the first source-follower, injected before the analog gain, so it is amplified exactly like the signal.
- Post-gain read noise $\sigma_{\text{post}}$ is everything added after amplification: the analog-to-digital converter and the downstream electronics. The gain never touches it.
Write the analog gain as $g$ (in DN per electron), rising with ISO. The mean recorded value is $\mu = g\,N$ (DN), and the three variances add, each in the domain it lives in. Referred to the output (DN$^2$):
This is the same affine line $\sigma^2 = a\,\mu + b$, now with its constants named by physics: the slope $a=g$ is the gain, so it rises with analog gain (not necessarily with every nominal ISO step), and the intercept $b = g^2\,\sigma_{\text{pre}}^2 + \sigma_{\text{post}}^2$ is the read-noise floor, a sum of a term the gain amplifies and a term it does not. (The photon term reads $g\,\mu$ because in electrons its variance is $N=\mu/g$, amplified by $g^2$.)
The revealing move is to refer that floor back to the input, dividing by $g^2$ to read it in electrons:
As ISO climbs, the post-gain term shrinks as $1/g^2$ and the input-referred read noise falls toward the floor $\sigma_{\text{pre}}$. That single curve, read noise in electrons versus ISO, captures a sensor's low-light behavior (Figure 2.8.13).
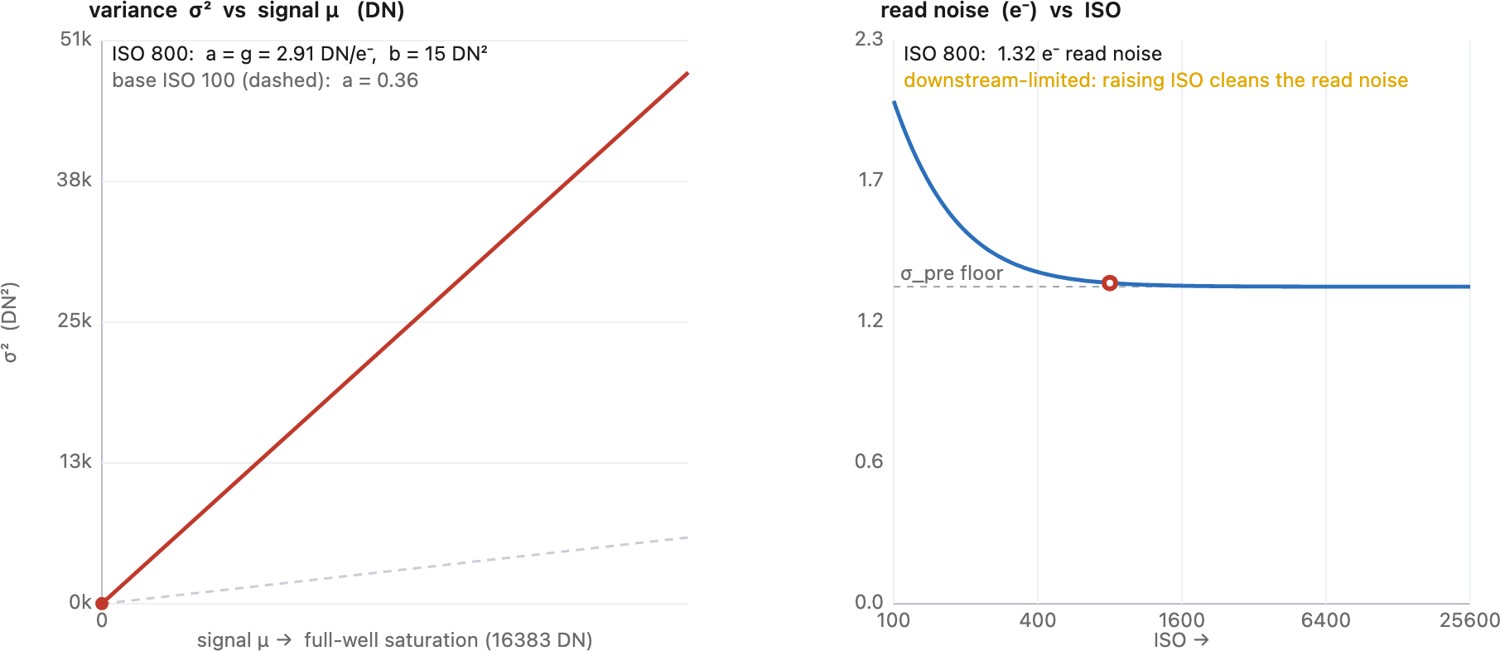
Within a fixed readout mode we approximate the pre- and post-gain terms as constants. The following illustrative cases show how their relative sizes change the result; they are not measured decompositions for named cameras. Let $g_0$ be base gain and express the downstream term as its input-equivalent value $\sigma_{\text{post}}/g_0$ at that gain.
| illustrative case | full well (e⁻) | pre-gain noise (e⁻) | downstream noise referred to base-gain input (e⁻) | total read noise at $g_0$ (e⁻) | at $4g_0$ (e⁻) |
|---|---|---|---|---|---|
| low downstream noise | 45,000 | 1.2 | 1.5 | 1.92 | 1.26 |
| very low downstream noise | 28,000 | 1.0 | 0.3 | 1.04 | 1.00 |
| moderate downstream noise | 50,000 | 1.3 | 2.0 | 2.39 | 1.39 |
| downstream-limited readout | 68,000 | 2.5 | 35.0 | 35.09 | 9.10 |
| small-well example | 6,000 | 1.5 | 2.0 | 2.50 | 1.58 |
For a real camera, measure or consult its input-referred read-noise curve for the relevant raw mode. Full well and read noise need not stay fixed across conversion-gain switches, bit-depth changes, or electronic-shutter modes. The table isolates analog gain to explain the mechanism.
What modern sensors do about it: ISO invariance and dual conversion gain. Two facts fall straight out of the input-referred equation. First, ISO invariance. If the pre-gain noise already dominates the floor at low ISO ($g^2\sigma_{\text{pre}}^2 \gg \sigma_{\text{post}}^2$), then $\sigma_{\text{read}}\approx\sigma_{\text{pre}}$ at every ISO, and raising ISO in the camera buys nothing that brightening the raw file in software could not. Such a sensor is called ISO-invariant: within such a gain range, a lower ISO can protect highlights while software lifting gives similar shadow noise. This does not establish that base ISO is always best: conversion-gain switches and other mode changes can alter the noise floor. On-chip ADCs reduce downstream noise, but the degree and range of ISO invariance remain camera-specific. The older arrangement, an off-chip ADC with large downstream noise (many DSLRs into the early 2010s), sat at the opposite extreme: $\sigma_{\text{post}}$ dominated at low ISO, so cranking the analog gain genuinely lowered the input-referred read noise, and "expose at the ISO you actually need" was real advice, not superstition. In affine-model terms, ISO invariance is just the statement that the input-referred intercept $b/g^2$ is already flat.
Second, dual conversion gain. A photosite cannot at once hold a huge charge (for highlight headroom in bright light) and convert that charge to voltage with tiny noise (for clean shadows in the dark); the conversion gain that trades between them is a hardware setting. Modern sensors refuse to choose and build two readout modes: a low-conversion-gain mode with a large full well and higher read noise for bright scenes, and a high-conversion-gain mode with a smaller well but markedly lower $\sigma_{\text{pre}}$ that switches in above a threshold ISO. On a read-noise-versus-ISO plot this appears as a sudden step down at that ISO (the drop near ISO 500-800 on many bodies), where a higher ISO is actually cleaner than a slightly lower one. In our model the switch changes the physical constants themselves: at the threshold both $N_{\text{full}}$ and $\sigma_{\text{pre}}$ drop, so the noise profile must be calibrated on both sides. Whether a plotted slope or intercept rises or falls also depends on gain and output normalization. The affine model is then not one line across all ISOs but a family of lines with a break at the dual-gain point.
The upshot ties the section together: $a$ and $b$ are not sensor constants but functions of ISO, with $a\propto g$ and $b=g^2\sigma_{\text{pre}}^2+\sigma_{\text{post}}^2$; ISO invariance is the regime where the input-referred floor $b/g^2$ is flat; and dual gain is a deliberate step in $\sigma_{\text{pre}}$ (and full well) that resets both constants at a chosen ISO. A denoiser or raw pipeline handed the wrong $a,b$ for the ISO, or blind to the dual-gain break, mis-models the noise in exactly the shadows it is trying to protect.
2.8.7 Dynamic range⧉
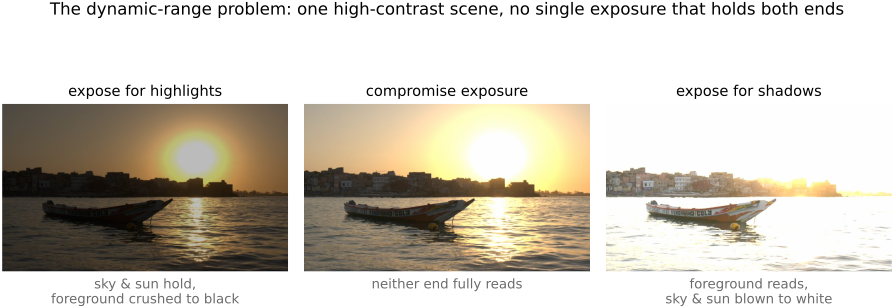
Two extremes bound what a single exposure can hold. At the top, a pixel's well saturates: once it has counted its full-well capacity of electrons, more light adds nothing and the highlight clips to white. At the bottom, the read-noise floor sets the dimmest signal still distinguishable from noise. The ratio of the two is the sensor's dynamic range: how much of a high-contrast scene a single exposure can capture. When a scene's range exceeds the sensor's (a bright window and a dim interior in one frame), no single exposure holds both ends, which is the motivation for high-dynamic-range (HDR) imaging, merging several exposures (Chapter 17.1, Dynamic range and multiple-exposure capture; Figure 2.8.14). Like everything else a photographer counts, dynamic range is quoted in stops (factors of two), which connects it straight to the exposure controls.
One subtlety keeps dynamic range from being the hard number it looks like: the bottom is not a sharp cliff where signal abruptly vanishes, but wherever the signal-to-noise ratio falls below what you are willing to accept. Engineers usually quote the engineering dynamic range, placing the floor at SNR = 1 (signal equal to noise); that is the most generous possible bound, and full-well divided by read noise approximates this criterion when read noise dominates at the threshold. With shot noise included, the electron signal $N$ at SNR $q$ solves $N/\sqrt{N+\sigma_r^2}=q$, giving $N_{\min}=(q^2+\sqrt{q^4+4q^2\sigma_r^2})/2$. The usable range is then $\log_2(N_{\mathrm{sat}}/N_{\min})$ stops, where $N_{\mathrm{sat}}$ is the effective saturation signal at the chosen gain. A photographer who wants genuinely clean shadows demands a far higher SNR, say 10 or 20, sets the floor higher, and counts fewer usable stops. This is why measurement sites report dynamic range at a stated quality threshold and their numbers disagree: the same sensor has a wide engineering range and a narrower photographic one. In this respect dynamic range behaves like depth of field: both carry a crisp-looking definition that actually rests on a chosen tolerance (an acceptable SNR here, an acceptable circle of confusion there), so the single figure you read off is only ever as hard as the criterion behind it.
There is one more limit that no sensor spec sheet lists: the lens. Bright parts of a scene scatter stray light inside the lens and camera body (faint reflections off every element surface, the diaphragm blades, and the barrel walls) that settle as a veil of light spread across the whole frame. This veiling glare, the diffuse cousin of lens flare, lifts the darkest tones off true black, adding a structured background and its shot noise. Even if the mean glare could be subtracted, its photon noise would remain; this differs from electronic read noise. It therefore caps the dynamic range a real photograph can reach below whatever the bare sensor could deliver, and it bites hardest exactly when dynamic range matters most, shooting a dim subject against a bright source. It is why lens coatings, hoods, and a clean front element buy real shadow contrast, and why the deepest blacks in a studio shot are easier to protect than those in a backlit scene. Flare and veiling glare get their full treatment as optical defects in Chapter 22.1, Aberrations and optical challenges (§10.1).
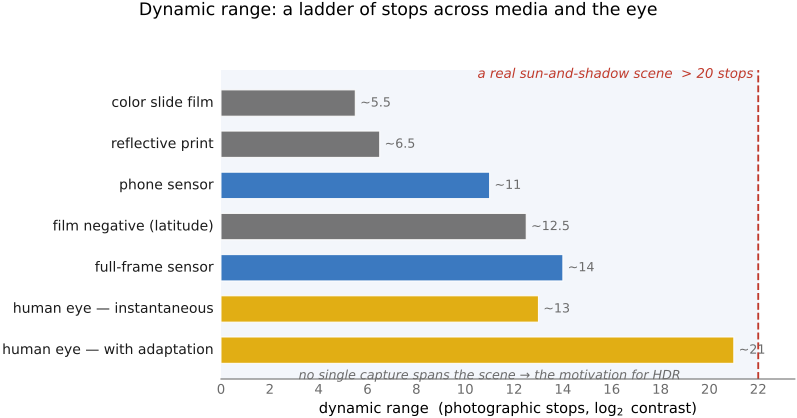
How wide a range, exactly? It helps to put numbers on it, because the dynamic ranges of real media and of the eye differ by a lot (Figure 2.8.15). A color slide is narrow, only about 5–6 stops; a reflective print about 6–7; a film negative is famously forgiving at roughly 12–13 stops of latitude; a phone sensor manages about 10–12 and a full-frame sensor about 14. The human eye sees about 10–14 stops instantaneously, but allow it to adapt (the slow re-centering of the retinal response covered with Chapter 3.3, Visual processing) and it spans 20+ stops over time; some animals do better still within their niche. Against all of these, an outdoor sun-and-shadow scene can exceed 20 stops in a single frame, which is precisely why no single capture holds it, and why HDR exists.
Recovering an underexposed shot: full-frame vs. phone. The clearest demonstration is to underexpose one. Shoot the same underexposed scene as raw on a full-frame camera and on a phone, then push the exposure up in software by three or four stops (Figure 2.8.16). The full-frame frame cleans up (its deep full-well and low read-noise floor give it the headroom to be lifted) while the phone frame breaks into shadow noise and banding, because lifting the exposure also amplifies its read-noise floor, which sat much closer to the signal to begin with. At matched framing, exposure, and output resolution, this illustrates the benefit a larger total collecting area can provide; it is not a universal rule that sensor size alone determines dynamic range, and exactly why phones lean on burst capture and HDR+ (Multiple-exposure part) rather than trusting a single exposure. It is also a coding exercise: see Exercises & Experiments.
A single exposure records from a top (the photosite's full-well capacity, where it saturates and clips to white) down to a bottom (the noise floor, the read noise that drowns the shadows). Their ratio is the dynamic range, quoted in stops. That floor is not absolute: it sits wherever the SNR drops below what you deem acceptable, so, just as with depth of field and its circle of confusion, the number depends on the quality criterion you pick (SNR = 1 gives the generous engineering range; a stricter SNR gives the narrower usable one). You widen it with a bigger well (larger photosites, why a full-frame sensor out-ranges a phone) or a lower floor (cooling, lower read noise), and you beat it altogether by merging multiple exposures (HDR). This is the capture-side companion to the quantization lesson below: what bounds a single shot is this range, full-well over floor, not the number of bits.
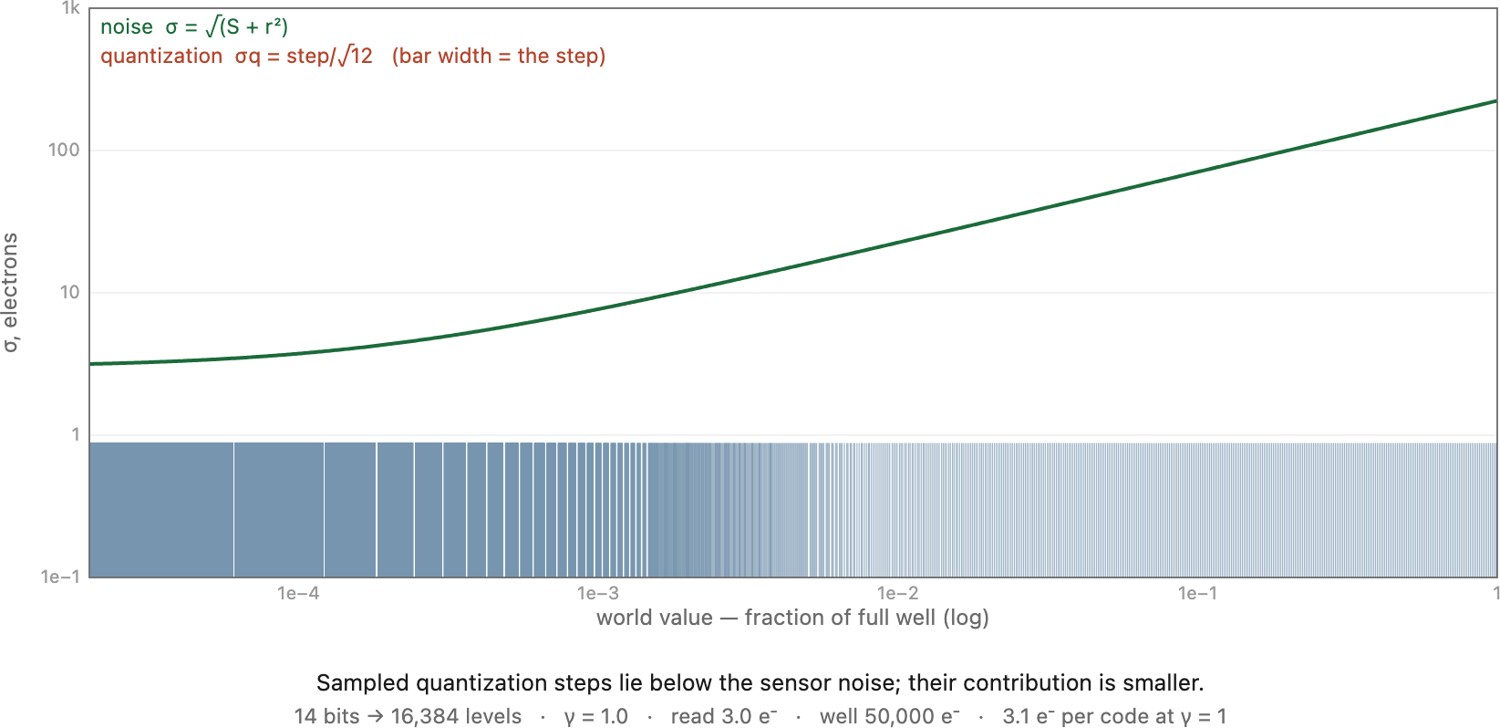
This is also the right moment to deflate a worry beginners often have about digital capture: that the image is quantized into a finite number of levels, and that this stair-stepping is what limits quality. With adequate raw bit depth and noise comparable to a code step, quantization is often a smaller limitation than sensor noise. Aggressive tonal edits or insufficient precision can still expose banding.
With enough bits and a sane encoding, what limits image quality is noise and dynamic range (the two quantities of this section), not the number of levels the analog-to-digital converter (ADC) offers. The noise floor and the full well bound what you can record; the quantization step, once it sits below the noise, is invisible. (Indeed, a little noise dithers the quantization, hiding it further.) Levels matter in one place: banding in the deep shadows of a linearly-encoded image, too few codes where the eye, working in ratios, is most sensitive, and that is exactly the problem gamma encoding exists to solve, by spending code levels perceptually (Chapter 4.1, Color space 101). So "rarely" is not "never." We meet this lesson again in BASIC → Image representation → Float vs 8-bit, where floats with headroom are the sane default.
These three facts (that noise is the jitter of a photon count, that the signal-to-noise ratio is worst in the shadows, and that dynamic range is the full-well-over-floor a single exposure can hold) recur on nearly every later page: in how a photographer exposes to the right, in high-dynamic-range merging (Multiple-exposure part), and in the denoising of the basic pipeline. With measurement and its limits now in hand, the part turns next to what a second viewpoint buys you (depth), and then to the eye that will finally judge the result.
2.8.8 Regimes, and how close we are to the limits⧉
Pulling the chapter together: which noise matters depends entirely on how much light you have, and a single picture usually spans several regimes at once.
- Bright light / highlights: shot-noise-limited. Plenty of photons, so shot noise ($\sqrt N$) dominates and read noise is negligible. SNR is excellent and only improves with more light; nothing but more photons (or a bigger sensor) helps.
- Deep shadows / low light: read-noise-limited. Few photons, so the constant read-noise floor dominates and sets where the image dissolves into mush. This is where sensor engineering still moves the needle and where computational averaging (bursts) buys real ground.
- Long exposures / heat: dark-current-limited. Time and temperature let thermal electrons pile up; cooling reduces the dark current; a master dark removes its mean pattern but cannot remove the random dark-current shot noise.
The same three regimes bound dynamic range, which is just full-well capacity ÷ read-noise floor L2.46: the top set by how many electrons a pixel holds before clipping, the bottom by the read noise.
How close are we to the theoretical limits? On two of the three axes, modern sensors are already close to their physical limits.
- Quantum efficiency, the fraction of arriving photons actually converted to electrons, is already around 80–95 % in good back-illuminated sensors, at favorable wavelengths before accounting for all camera-level losses. This leaves little efficiency gain there, but does not describe every wavelength, color-filter channel, or sensor. In bright light we are essentially at the shot-noise limit: a perfect sensor would be only marginally cleaner, because the noise is in the light itself L2.38.
- Read noise has fallen to ~1–2 electrons on the best CMOS, and specialized scientific CMOS and electron-multiplying sensors reach sub-electron read noise, within sight of counting individual photons (the single-photon avalanche diodes of the Advanced part do exactly that).
- Full-well capacity, and hence single-exposure dynamic range, is the axis still bound by pixel area and electrostatics, but readout architecture, added charge storage, and multiple conversion gains can extend it. A particular well has finite capacity; that does not imply that every sensor design has reached the same limit.
These limits explain the attraction of multi-frame computation: longer total collection improves photon statistics, averaging reduces independent read noise, and exposure bracketing extends the scene range beyond one capture. Sensor engineering and computation remain complementary. Improved efficiency, charge storage, readout, and optics still matter, especially outside the conditions where a particular sensor is already close to ideal.
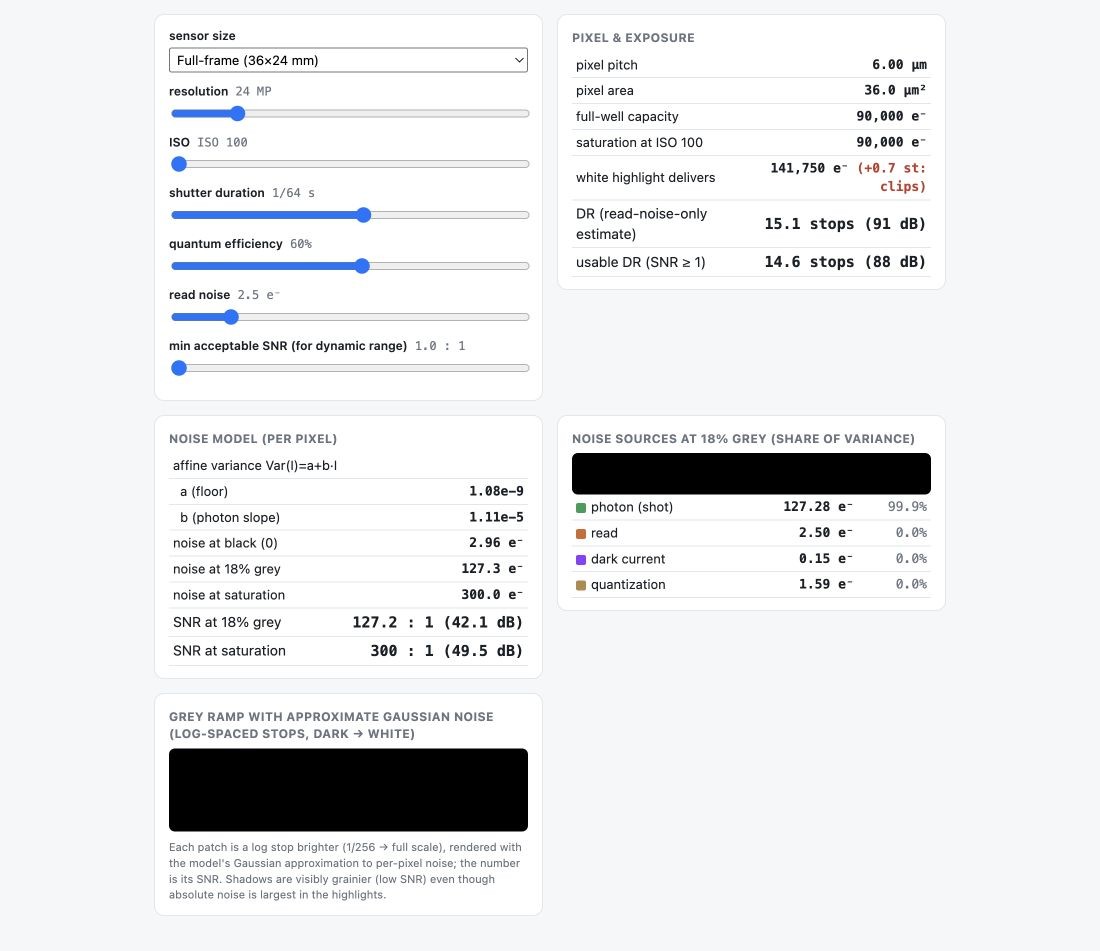
Figure 2.8.18 makes the budget concrete.
2.8.9 Making noise variance uniform⧉
The affine model above (#Noise variance is mostly affine in pixel brightness) is accurate but inconvenient: the noise variance changes with brightness, $\sigma^2(x) = a\,x + b$, so a bright patch is genuinely noisier, in absolute terms, than a dark one. Most denoising theory, though, is written for signal-independent noise, a constant-variance Gaussian everywhere. The bridge between the two is a variance-stabilizing transform (VST): a pointwise nonlinearity $f$ chosen so that $f(x)$ has (approximately) constant variance regardless of how bright $x$ is. Apply $f$, denoise in the stabilized domain with any off-the-shelf constant-variance method, then invert.
For pure Poisson (photon) noise, where $\sigma^2 = x$, the classical choice is the Anscombe transform (Anscombe 1948 (variance-stabilizing transform)),
whose output has variance $\approx 1$ once counts are sufficiently large (the $3/8$ is a small correction that keeps the approximation good down to a handful of photons). A real sensor is Poisson plus read noise, exactly the affine $a\,x + b$ of this chapter, and the generalized Anscombe transform (GAT) (Starck, Murtagh & Bijaoui, Image Processing and Data Analysis (1998)) handles that,
with $a$ the photon-gain slope and $b$ the read-noise variance, both measured as in this chapter, with black level already removed and $a>0$. Stabilization is approximate at very low counts, and clamping the radicand handles negative noisy samples. The one subtlety is the way back: naively inverting $f$ biases the result, because a mean does not survive a nonlinear map, so the exact unbiased inverse of Mäkitalo and Foi (Mäkitalo & Foi 2013 (generalized Anscombe)) is what you actually apply. The pipeline is stabilize, denoise as if Gaussian, invert, and it is why a great deal of raw denoising quietly runs in an Anscombe domain.
Gamma helps too, more crudely and for free. A gamma encoding compresses the highlights, where Poisson noise is largest in absolute terms, and stretches the shadows, so a square-root-like encoding can make the absolute encoded variance flatter in shot-noise-dominated regions, one more reason processing and viewing so often happen in an encoded space (Chapter 4.3, Encoding: linear, gamma or log). It is not a true variance-stabilizer, the variance is only roughly equalized and the curve was chosen for perception rather than statistics, but it can help over a restricted range. A log transform is different: the delta method gives variance approximately proportional to $1/x$ for pure Poisson input, so it does not stabilize shot-noise variance. Neither encoding recovers SNR lost during capture.
Recap: big lessons of this chapter
Two numbers describe noise spread, and both exist for a reason. Variance (the mean squared deviation) is the quantity the mathematics wants: it is additive for independent sources, exactly what we just used, and the basis of the $1/\sqrt N$ averaging law in Part 13, Denoising; it is the second moment that falls out of every Gaussian and least-squares derivation, and it composes cleanly under linear operations. But its units are squared (squared gray-levels, squared photons), so it means nothing to the eye. The standard deviation $\sigma$ (its square root) is the one people should read: it is back in the original units, directly comparable to the signal: the "$\sigma$" of error bars and the grain you actually see. Rule of thumb: derive and combine in variance, report in standard deviation.
Even a flawless sensor is noisy, because light itself is grainy: photons arrive as discrete, randomly-timed events, so the count in any fixed interval follows Poisson statistics ($\sigma=\sqrt N$), and no electronics can remove it: the randomness is in the light, not the chip. The only true cure is collecting more photons: a bigger pixel, a wider aperture, a longer exposure, or averaging many frames. Raising ISO is not a cure: it is gain applied after capture, amplifying signal and shot noise together. This irreducible floor is why bigger sensors win, why shadows are noisy, and what every denoiser later in the book is ultimately fighting.
Sensor noise is a sum of distinct sources whose variances add, but each rules a different regime, so diagnosing a noisy image means asking which one you are seeing. Photon shot noise ($\propto\sqrt{\text{signal}}$) dominates the midtones and highlights, and any well-lit shot. Read noise is signal-independent and dominates the deep shadows and short exposures, setting the floor. Thermal / dark-current noise grows with exposure time and temperature: the long-exposure and astrophotography enemy. Quantization matters only with too few bits L2.47. And fixed-pattern noise / PRNU (static per-pixel gain and offset variation) reads as a structured pattern and is removed by calibration (dark and flat fields). Match the symptom to the source before reaching for a fix.
Add the readings of $k$ small pixels and you get the same Poisson (shot) noise as one big super-pixel that caught the same photons, but you pay the read noise $k$ times, once per read-out, instead of once. So the only fundamental advantage of a bigger pixel (or one longer exposure) over many smaller ones is the read noise, not the photon statistics, as long as no light is lost in the gaps. The same holds for aggregating along any dimension: summing $k$ short exposures, or $k$ burst frames, keeps the shot noise of the total light but charges read noise $k$ times. This is precisely why charge-domain binning (combine, then read once) beats digital summation (read $k$ times, then add) in the dark.
Shot noise is Poisson, so its variance grows linearly with the signal ($\sigma^2 \propto N$) and its standard deviation grows only as the square root ($\sigma \propto \sqrt{N}$). Two consequences pull in opposite directions: the absolute noise is larger in highlights than in shadows (a 10,000-photon highlight has $\sigma=100$; a 100-photon shadow has $\sigma=10$), yet the SNR $= N/\sqrt{N} = \sqrt{N}$ is higher in the highlights: the signal outgrows the noise. So bright areas are noisier in absolute terms but cleaner to the eye; the shadows have the worst SNR (Figure 2.8.4, Figure 2.8.6). This is why exposing to the right and brighter scenes look smoother, and why we gamma/log-encode so equal ratios get equal steps.
The variances add, and two terms dominate: shot noise contributes an amount proportional to the signal (Poisson, variance = mean, scaled by the gain) and read noise a constant floor. So the total is variance ≈ gain·signal + read², a straight line in brightness (Figure 2.8.7). The slope is the photon gain (it steepens with ISO, which amplifies the signal and its shot noise together); the intercept is the read-noise floor. We can measure it without any model: take an aligned burst of a static scene and, per pixel, plot the variance across frames against the mean. This affine law is a statement about the variance and is essentially exact for the two dominant sources; it says nothing yet about the shape of the distribution. Where the electron count is large, a single pixel's value over many frames does look ≈ Gaussian (Figure 2.8.8), which licenses modeling per-pixel noise as additive Gaussian in the midtones and highlights. That bell is only an approximation, though: the shot term is really Poisson (variance = mean, but discrete, skewed, and non-negative), and in the deep shadows, where only a handful of electrons land, it stops looking Gaussian at all. The additive-Gaussian model is a convenience of the well-exposed regime, not a law of noise in general (we pin down where it breaks below).
A recorded value is clamped to $[0,\text{max}]$. Near black the negative half of the noise is cut off and frames pile up at 0; near white the positive half is. So at the extremes the noise distribution is asymmetric, with its mean pushed inward (Figure 2.8.12). The consequence for denoising: a naive average or smoothing returns that biased mean, so it makes shadows come out too bright and highlights too dark: a bias every denoiser must correct for (we return to it in Denoising, BASIC).
The top rail is not a hard wall. Read noise is added after the charge saturates at the well (clip 1) and before the ADC clamps (clip 2), so a pixel pinned at full well is digitized to $g\,N_{\text{full}}+B$ plus a zero-mean Gaussian excursion: about half of all saturated pixels read strictly below $\mathrm{DN}_{\max}$, by up to a read-noise's worth. It makes no difference how far over-range the pixel truly is: a highlight ten times too bright still only fills the well to $N_{\text{full}}$, gets the same read noise, and lands below the maximum half the time. So a measured value just under the ceiling does not prove a pixel was unsaturated, and a patch of genuinely clipped highlights reads a little spread of values, not one flat number. Anything that must know what saturated (HDR-merge pixel rejection, highlight reconstruction, clipping warnings) has to threshold a few $\sigma_r$ below $\mathrm{DN}_{\max}$, never exactly at it.
A single measured value is built in four stages, in the order the sensor applies them: (1) Poisson photon shot noise, whose variance equals its mean, the irreducible floor; (2) saturation at the well, a hard clip of the electron count at the full-well capacity; (3) additive Gaussian read noise, the electronics' contribution, applied after the charge is held; and (4) the ADC clip to $[0,\mathrm{DN}_{\max}]$, after gain and the black-level pedestal. Do it in electrons, the only unit in which shot noise is exactly Poisson. The tidy affine Gaussian ($\sigma^2=a\,I+b$) is just the well-exposed limit of this recipe with the Poisson shape and both clips dropped, which is why it matches in the midtones and parts from the truth in the deep shadows (skewed, floored) and at saturation (a soft, spread-out ceiling). The order matters: because read noise lands between the two clips, saturated highlights do not pile up as a clean spike (see the two clipping lessons above). Get it right and you reproduce real noise; get it wrong and your simulator, training data, or denoiser is fitting a sensor that does not exist.
A single exposure records from a top (the photosite's full-well capacity, where it saturates and clips to white) down to a bottom (the noise floor, the read noise that drowns the shadows). Their ratio is the dynamic range, quoted in stops. That floor is not absolute: it sits wherever the SNR drops below what you deem acceptable, so, just as with depth of field and its circle of confusion, the number depends on the quality criterion you pick (SNR = 1 gives the generous engineering range; a stricter SNR gives the narrower usable one). You widen it with a bigger well (larger photosites, why a full-frame sensor out-ranges a phone) or a lower floor (cooling, lower read noise), and you beat it altogether by merging multiple exposures (HDR). This is the capture-side companion to the quantization lesson below: what bounds a single shot is this range, full-well over floor, not the number of bits.
With enough bits and a sane encoding, what limits image quality is noise and dynamic range (the two quantities of this section), not the number of levels the analog-to-digital converter (ADC) offers. The noise floor and the full well bound what you can record; the quantization step, once it sits below the noise, is invisible. (Indeed, a little noise dithers the quantization, hiding it further.) Levels matter in one place: banding in the deep shadows of a linearly-encoded image, too few codes where the eye, working in ratios, is most sensitive, and that is exactly the problem gamma encoding exists to solve, by spending code levels perceptually (Chapter 4.1, Color space 101). So "rarely" is not "never." We meet this lesson again in BASIC → Image representation → Float vs 8-bit, where floats with headroom are the sane default.