28.3 Auto curation⧉
Auto-curation is the machine doing the culling: scoring each shot for technical quality (is it sharp, is it exposed, are the eyes open) and for learned aesthetics, grouping the near-duplicate bursts and keeping only the best of each, then assembling a small, diverse highlight set. Three kinds of criteria are really in play, and they pull in different directions: technical quality (sharpness, focus, noise), aesthetic quality (the learned sense of what makes a good photograph), and personal relevance (whether this shot matters to you: the people, places, and moments you care about). Technical measurements are comparatively concrete, but whether a blur or a clipped highlight spoils the picture still depends on intent; the last is the one no generic model can score on your behalf, and it is why fully automatic curation can only ever propose, not decide. It is the selection problem that a firehose of images forces on anyone who shoots digitally, and it sits one rung above retrieval (Chapter 28.2, Retrieval): retrieval finds the images that match a query, curation finds the ones that are good and discards the rest. The pipeline reads like a triage. Reject the technically broken (blurry, blown-out, blinked), then score the survivors for appeal, collapse the near-duplicate bursts to their best member, and finally choose a set that is both good and varied. It uses some of the same machinery as retrieval, but the goal is selection rather than matching.
28.3.1 Technical quality: the easy rejects⧉
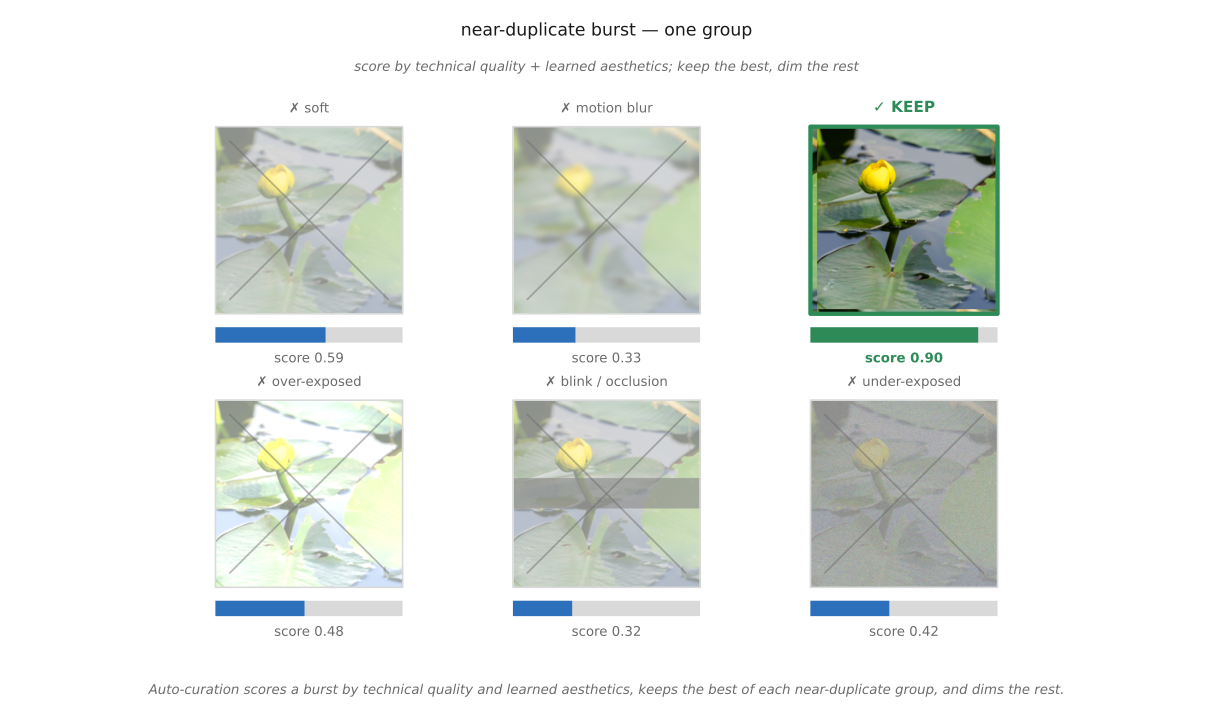
The first stage measures likely technical problems. Gradient energy or Laplacian variance can help compare sharpness in similar frames, but scene texture and noise also raise them. A sharp blank wall can score below a blurred textured wall. Histogram mass at the endpoints flags possible clipping, not necessarily an exposure mistake: a black background or a specular light source may legitimately reach an endpoint, and rendered-image clipping differs from RAW saturation. Noise estimates also depend on texture and processing. These scores are cheap screening signals, especially within a burst; they are not certain grounds for discarding an image.
Faces are special, and they get their own detectors, because a frame can be flawless by every signal statistic and still be a reject the instant you look at the people in it. The two cues that matter most are eyes-open / blink detection and smile / expression scoring. A group portrait with one person blinking is usually unusable, which is why the "best shot" features on phone cameras lean so heavily on these face cues. Google's Top Shot uses face and frame-quality cues to recommend moments around the shutter press (Figure 28.3.1). Top Shot is the best-documented instance and a clean technical reference for this whole stage (Google, Top Shot on Pixel 3, 2018): the system considers up to 90 frames spanning about 1.5 seconds before and after the shutter press, and an on-device MobileNet scores each frame in real time on a deliberately layered set of attributes. Early layers catch the cheap, functional defects (is it sharp, is it exposed); deeper layers spend their parameters on objective facial cues (are the eyes open, is the subject smiling) and finally on subjective ones (is there an expression of genuine amusement or surprise), and the scoring system combines these with motion, exposure, and gyro signals into one frame-quality score, so the phone can quietly hand you back a better frame than the one your thumb chose. Its descendant Best Take (Pixel 8) goes one step past selecting a frame to compositing one by swapping each person's face for their best expression across a short burst, so the group photo where someone always blinked finally has everyone smiling at once (a composite that may depict expressions that did not occur simultaneously). The lesson of this stage is that a great deal of culling is just defect rejection, and defect detection is useful for proposing rejects, but the photographer still decides whether a flagged property matters.
28.3.2 Aesthetics: the hard, learned part⧉
A photo can be technically fine and still uninteresting. The second stage of the triage is the one that tries to predict appeal, and unlike the first it has no clean ground truth, so it is learned from large datasets of human-rated photographs. The reference corpus is AVA (Murray, Marchesotti & Perronnin 2012), a quarter-million images each carrying a distribution of scores from a photography-contest community. The standout method is NIMA (Neural Image Assessment) of Hossein Talebi and Peyman Milanfar (2018). Its main design choice is to predict the full distribution of human ratings rather than a single quality number: NIMA fine-tunes an ImageNet classification network to predict the entire distribution, using an Earth-Mover's-Distance loss over the 1–10 scale. That distribution captures both the mean rating and how much raters disagree. A photo that everyone rates a flat 5 and a photo that half the crowd loves and half hates can share a mean and yet be wildly different pictures, and predicting the spread tells them apart.
The caveat here is the reason this subsection cannot be read as a verdict. Aesthetics is subjective and culturally loaded (Part 40, Human factors). A learned scorer does not encode beauty; it reflects the average taste of its annotators, in AVA's case the conventions of one online photography community at one moment in time. That average is genuinely useful for ranking a personal collection, which is all the curation pipeline asks of it, but it is not a pronouncement on whether a photograph is any good. Worse, by construction it regresses toward the conventional, so it systematically undervalues the unconventional: the deliberately off-kilter, the anticliché shot that is interesting because it breaks the rules the annotators rewarded (Chapter 28.10, Artistic projects with photo collections). The anticliché camera is curation's contrarian twin, and the gap between them is exactly the gap between "what the crowd scores highly" and "what is worth keeping." A curation system that only ever surfaces the high-scoring frame will quietly flatten a collection toward the postcard, and knowing that is part of using the scorer well.
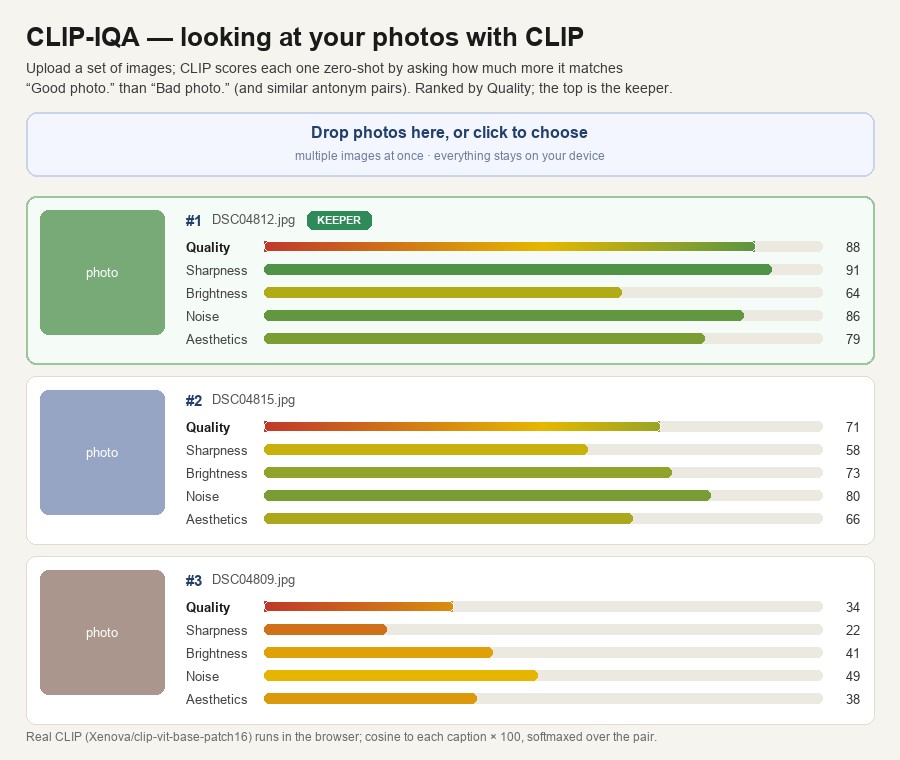
The cleanest way to feel a learned scorer is to run one, and one useful variant needs no rated dataset: CLIP-IQA Wang, Chan & Loy 2023 (CLIP-IQA). Where NIMA must be fine-tuned on AVA, CLIP-IQA is zero-shot and reuses CLIP's shared text–image space (Chapter 28.2, Retrieval). It scores a photo by asking CLIP how much more the image matches the caption "Good photo." than "Bad photo." (the cosine similarity to each prompt, softmaxed over the pair), and the same antonym trick, swapped for "Sharp."/"Blurry.", "Bright."/"Dark.", "Clean."/"Noisy.", or "Beautiful."/"Ugly.", reads off sharpness, brightness, noise, and aesthetics with no training of its own. The interactive demo below runs the real CLIP model in your browser: drop in a set of your own photos and watch it score and rank them, flagging the top-quality frame as the keeper exactly as the curation pipeline would (Figure 28.3.2). It also makes the caveat concrete: if you feed it a deliberately unconventional shot and watch the "Good photo." score sag, for reasons that have nothing to do with whether the picture is worth keeping.
28.3.3 Grouping, summary, and diversity⧉
The single biggest win on a real camera roll is often near-duplicate grouping. Bursts, re-tries, and the reflexive habit of firing three shots to be safe produce clusters of nearly identical frames, and the obvious move is to group each cluster and keep only its best member. The grouping reuses the very machinery of the previous section: the same learned embeddings that let Chapter 28.2, Retrieval rank a database by similarity also place near-duplicate frames almost on top of each other in the embedding space, but semantic similarity alone can merge distinct moments. Combine it with capture time and instance-level comparison before treating frames as redundant. Within each cluster, the technical-quality and aesthetics scores from the earlier stages pick the keeper: the sharpest frame, the one where nobody blinked, the best-composed of the bunch (Figure 28.3.1). This is where the four-thousand-to-twelve compression mostly happens, and it is the stage that most reliably matches what a human editor would do by hand.
But picking the best of each cluster is still not enough. A highlight reel of the twelve highest-scoring photos is very often twelve takes of the same hero shot, such as one gorgeous sunset photographed a dozen ways, each version scoring high and each crowding out everything else the trip contained. The fix is to make diversity an explicit objective rather than a hoped-for side effect. Summary selection adds a coverage or diversity term, often formalized through submodular maximization, where each added photo's marginal value shrinks as the set already covers what it would have contributed, or as a clustering over the collection's people, places, and moments, so the kept set spans the trip instead of dwelling on its single best moment. Quality alone ranks; quality-plus-diversity summarizes. This is the same problem that Chapter 28.4, Life logging cameras makes acute, where a day of passive capture must be compressed not to its prettiest frames but to a faithful, varied account of the day, and it is the stage where curation stops being a filter and becomes an editor.
28.3.4 Arranging the collection after culling⧉
Culling answers what to keep; it leaves open the other half of curation: how to lay the keepers out so a person can actually browse them. A grid sorted by date is useful for remembering events, but it can scatter visually related pictures across months. Content-based alternatives lay a collection out by content, turning the screen itself into a map of the archive, and three are worth seeing, each with its own interactive viewer elsewhere in this part: the photomosaic in Chapter 28.1, Photo Mosaics, and the kd-tree and self-organizing-map layouts in Chapter 28.12, Displaying images together.
A kd-tree layout is the space-filling one. It recursively partitions the canvas (alternating horizontal and vertical cuts) until every photograph has its own cell, packing the whole collection into one screen with no overlap and no scrolling, the rectangles sized so important or higher-scoring shots get more room. A photomosaic goes further and makes the arrangement itself depict something: the photos are placed so that, squinted at from a distance, they reproduce a target picture, while up close they remain the individual photographs of the collection, arranged to depict a larger target image (the full treatment is in Chapter 28.1, Photo Mosaics). And a self-organizing map (SOM) is the learned layout: a 2-D grid trained so that visually similar photographs land in neighboring cells, using the very embeddings that drove Chapter 28.2, Retrieval, so the map becomes a similarity atlas you navigate by content, beaches in one region, faces in another, sunsets in a third. Each is a different answer to the same question the rest of this section dodged: once the firehose is culled to its keepers, the arrangement is what makes them browsable, and the layout can carry as much of the curation as the culling did.
Curation is retrieval pointed at quality and diversity instead of similarity. It uses the same embeddings, the same nearest-neighbor machinery, the same "image as a point in a space," but where retrieval asks what matches this?, curation asks what is worth keeping? and answers it as a triage: reject the measurably broken first (sharpness, exposure, blink: interpretable, certain, nearly free), score the survivors for learned aesthetics second (useful for ranking, never a verdict, since it encodes the crowd's average taste and undervalues the anticliché), then collapse near-duplicate bursts to their best member (the biggest real-world win), and finally select for diversity so the keepers span the collection rather than re-shooting its one hero moment. The order is the design: certainty up front, taste at the back. One caveat survives the whole pipeline: every late stage encodes whose taste, which is why the same machinery that culls a vacation roll so well also quietly flattens it toward the conventional.
Recap: big lessons of this chapter
Curation is retrieval pointed at quality and diversity instead of similarity. It uses the same embeddings, the same nearest-neighbor machinery, the same "image as a point in a space," but where retrieval asks what matches this?, curation asks what is worth keeping? and answers it as a triage: reject the measurably broken first (sharpness, exposure, blink: interpretable, certain, nearly free), score the survivors for learned aesthetics second (useful for ranking, never a verdict, since it encodes the crowd's average taste and undervalues the anticliché), then collapse near-duplicate bursts to their best member (the biggest real-world win), and finally select for diversity so the keepers span the collection rather than re-shooting its one hero moment. The order is the design: certainty up front, taste at the back. One caveat survives the whole pipeline: every late stage encodes whose taste, which is why the same machinery that culls a vacation roll so well also quietly flattens it toward the conventional.